Image and Video Generation AI News — 2026-09-20
Open-source models—especially China-originated models such as Qwen, Wan, and MiniMax-H3—are rapidly gaining ground as the fallback for users who have exhausted closed-source free tiers. Meanwhile, the X stage yielded no usable data because irrelevant search terms were used, leaving this report effectively supported by only five platforms.
Image and Video Generation AI News Roundup — Closed Source vs. Open Source — 2026-09-20
Hey! This time, I speed-ran checks across six platforms—Reddit, X, YouTube, Bluesky, Lemmy, and Pinterest 🔥🔥 The bottom line: the closed-source camp (Google Veo/Nano Banana, Sora 2, Midjourney, Kling, Seedance, and others) remains the star of the news cycle, and synchronized audio is seriously becoming a standard feature. But the open-source camp—especially China-based players like Qwen, Wan, and MiniMax-H3—is catching up at an incredible pace, becoming a very visible refuge for users once their free tiers run out 🚀 One quietly important point: backlash against AI-generated content is bigger in places where ordinary people gather than in AI enthusiast communities 😤. To be candid, though, the X stage was a complete miss, so this report is effectively based on five platforms 🙏
Across platforms
- The momentum behind open source is seriously unstoppable: Reddit (Wan, MiniMax H3, and Krea2 are repeatedly mentioned as alternatives after closed-source free tiers run out), Lemmy (more than 15 ComfyUI tools for MiniMax-H3 were posted in September alone in the
!stable_diffusioncommunity), and YouTube (Qwen-Image → Qwen-Image-2512 → Z-Image, and Wan 2.5 → 2.6 → 2.7, with near-monthly updates) all tell the same story. Open source is increasingly becoming synonymous with “free, high quality” 💪 - Closed-source video generation is making audio standard: The same trend appears on Bluesky (Kling 3.0’s synchronized audio, announced by Replicate; Seedance 2.0’s integrated audio-video generation) and YouTube (Grok Imagine 1.5 is presented as generating dialogue and ambient sound simultaneously) 🎬🔊
- Google’s Veo/Nano Banana line has become the face of closed source: This is confirmed three ways: Pinterest repeatedly uses Veo’s warm Pixar-like footage as viral imagery; YouTube’s Theo - t3.gg flatly says “Google won image generation”; and Reddit is talking about expanded free credits for Google Flow 👀
- Backlash against AI-generated content is exploding outside AI-fan circles: Reddit (354-point outrage over ArtPrize allowing AI works, plus 63-point complaints about workplace AI-image quotas), Lemmy (the anti-AI community
!fuck_aihas 9,179 monthly active users and is among Lemmy’s largest), and Pinterest ("Real vs AI" authenticity quizzes have become their own genre) all convey the same mood 😨 - Primary information comes more from individuals than official companies: Bluesky has near-silence from official corporate accounts, leaving individual researchers such as Simon Willison and hosting providers like Replicate as information sources. On YouTube, weekly roundups by individual channels such as AIPOD-CAST and Lev Selector serve as news sources. Few official corporate channels are acting as primary publishers, which seems to be a cross-platform pattern 📢
Platform by platform
Reddit: Collected 12 threads across nine subreddits, short of the target of 20. Multiple threads repeated that open-source options (Wan, MiniMax H3, Krea2) are becoming the escape route once closed-source free tiers run dry. Opinions on GPT Image 2.5 Flare were sharply split between the “incredible” camp and the “it looks just like Krea2” camp 😂 The surprising part was that general communities (354-point ArtPrize backlash) and work-focused communities (63-point designer complaints) were hotter than AI-tech subreddits.
X: Honestly, this was a total accident 🙈 The 40 collected posts merely searched general trends from the connection region (around Croatia), such as “Greenland,” “#Bitcoin,” and “Chelsea,” and contained zero posts about image or video generation AI. So X provided no closed- or open-source insights whatsoever this time. This is a clear gap in a platform explicitly named in the brief 🕳️
YouTube: Checked 12 videos. Closed-source channels (Theo, Astrovah, Woollyfern, which specializes in monthly Midjourney updates, and FixNode) and open-source channels (Bijan Bowen, HitPaw, MaxonShire, Promptus AI) are neatly divided. Open-source creators emphasize “ComfyUI,” “running locally,” and “free,” while closed-source creators focus on quality and features. It was unfortunate that the JavaScript-heavy search pages made it nearly impossible to obtain view counts or subscriber numbers 😅
Bluesky: Because the official search API was repeatedly blocked with 403 errors, the approach switched to following posts from individual researchers (Simon Willison, Max Woolf, Ethan Mollick) and Replicate’s official account. Nearly every post found concerned closed-source models—GPT Image 2, Runway Gen-4.5, Kling 3.0, Seedance 2.0, and Vidu Q3. No active community accounts for open-source models were found; the only plausible one had stopped posting in February 2025. It was also amusing that images of a pelican riding a bicycle have become a running model-comparison joke 🐦🚲
Lemmy: This had the best balance, with open and closed source clearly separated. On the open side: a rush of MiniMax-H3 activity in !stable_diffusion and the new model Boogu-Image-0.1 (Apache-2.0, 10 billion parameters). On the closed side: Google’s Nano Banana 2 Lite, Microsoft’s MAI-Image-2.5, long-form storytelling experiments with Sora 2, and the surprising news that Midjourney is pivoting to medical spas 😲 Lemmy’s anti-AI community !fuck_ai (8,252 subscribers) was also a distinctive finding.
Pinterest: Thirty of 50 pins pre-collected by a worker were examined, including their images. Closed-source tool lists and recycled “AI NEWS” thumbnail templates are being mass-produced, while open source is almost entirely absent—the only exception was a single local tool called Amuse 3.0. Google Veo footage is reused constantly, and “Is this AI or real?” authenticity quizzes have clearly become a genre 🎨
What to watch
- The rapid growth of ComfyUI tools for MiniMax-H3 (Lemmy
!stable_diffusion, e.g. https://github.com/nazgut/ComfyUI-MiniMaxH3-CLSS) — a potential new leading player in open-source video generation 🔥 - Sora 2’s “production memory” problem (via Reddit on Lemmy, https://lemmy.durstig.online/post/59922) — maintaining consistency in long-form work may be the next barrier, rather than making isolated clips
- The theory that Google Nano Banana Pro is running away with the market (YouTube, Theo - t3.gg, https://www.youtube.com/watch?v=UV9GqinedQ8) — is it really at a “no Photoshop needed” level? Watch for follow-up coverage
- The GPT Image 2.5 Flare vs. open-source Krea2 debate (Reddit, https://www.reddit.com/r/ImagineAiArt/comments/1wi79wi/) — the advantage of paid services themselves is starting to be questioned
- ArtPrize’s acceptance of AI works (Reddit r/grandrapids, https://www.reddit.com/r/grandrapids/comments/1wi4ub0/) — could become an indicator of where mainstream society draws the line
- Midjourney’s medical-spa pivot and Hollywood disclosure demands (Lemmy, https://lemmy.zip/post/66397234 ,https://lemmy.today/post/56011946) — potential corporate credibility risks are emerging
Recommendations
- Recollect the X stage using directly relevant search terms such as "Sora 2" "Midjourney" "Stable Diffusion" "Runway Gen" "Kling AI" "open source image generation".
- Put release frequency for China-originated open-source players such as MiniMax-H3, Qwen, Wan, and Z-Image on every run’s watchlist.
- Keep tracking reactions in general and professional communities, not only AI-specialist subreddits, because backlash signals are stronger there.
- Test ways to work around Bluesky’s official search API 403 issue before the next run.
- Continue following Sora 2’s “production memory” problem and Midjourney’s medical-spa pivot in the next run.
- Collect Pinterest data with genre tags so open and closed source can be classified mechanically.
Data quality
The X stage used search terms unrelated to the topic—geopolitics, cryptocurrency, soccer, and so on—so none of its 40 collected posts were relevant and it provided no usable data. Reddit (12 items) and Bluesky (roughly 12 items extracted through individual accounts because the search API was blocked) also fell short of the brief’s completion criterion of about 20 posts per platform. Pinterest and YouTube had partial limitations as well: Pinterest lacked genre tags and live browsing, while YouTube view and subscriber counts could not be retrieved because they depend on JavaScript. Still, sufficient information was obtained for the main takeaways. Lemmy and YouTube were relatively solid, providing specific insights for both open and closed source.
Platform summaries
Reddit — Image and Video Generation AI News
Where
The 12 collected threads came from nine subreddits.
| Subreddit | Members | Collected threads |
|---|---|---|
| r/generativeAI | 154,961 | 4 |
| r/graphic_design | 2,929,382 | 1 |
| r/GeminiAI | 375,783 | 1 |
| r/grandrapids | 161,719 | 1 |
| r/aitubers | 28,785 | 1 |
| r/ImagineAiArt | 19,335 | 1 |
| r/AIToolTalks | 6,757 | 1 |
| r/aifilmmaking | 8,200 | 1 |
| r/aivideomaking | 7,267 | 1 |
r/generativeAI is the central hub focused directly on AI image and video generation (four threads). r/GeminiAI and r/ImagineAiArt feature experiences with closed-source models; r/aifilmmaking and r/aivideomaking focus on video-production practice; r/grandrapids and r/graphic_design show reactions when AI-generated content collides with real-world settings such as art competitions and workplaces; and r/AIToolTalks serves as an outlet for broader AI anxiety.
What people say
- Thread 1, “Which AI video generator can still be used for free?” (r/generativeAI, 18 points, 57 comments, 2026-09-16) https://www.reddit.com/r/generativeAI/comments/1whtesl/ — Open source/local generation (Wan, MiniMax) has become the escape route after closed-source free tiers are exhausted. u/RioMetal: “If you can go local you have plenty of them, like Wan or Minimax”
- Thread 2, “GPT Image 2.5 Flare — is this actually the best AI image generating model right now?” (r/ImagineAiArt, 84 points, 60 comments, 2026-09-16) https://www.reddit.com/r/ImagineAiArt/comments/1wi79wi/ — Opinions are split down the middle. u/oldboi777 praises it as an “incredible upgrade,” while u/SeaworthinessFresh16 argues, “The result in Comfyui with Krea2 looks the same,” saying it is not meaningfully different from open-source Krea2.
- Thread 12, “Need a good video generation AI for image to video of people” (r/generativeAI, 0 points, 22 comments, 2026-09-15) https://www.reddit.com/r/generativeAI/comments/1wh1y9d/ — The post mainly complains about censorship filters in closed-source tools (Google Flow / Nano Banana Pro). u/f5alcon says, “Minimax H3 is the best local generator,” while u/jworm0624 recommends, “Krea 2 turbo for images, minimax h3 for videos. All on comfyui,” positioning open-source options as alternatives.
- Thread 7, “Google Flow is giving creators a surprisingly generous amount of free AI video generation right now” (r/aifilmmaking, 8 points, 7 comments, 2026-09-14) https://www.reddit.com/r/aifilmmaking/comments/1wg7izt/ — Closed-source Google Flow/Veo has expanded free credits and is evolving from simple text-to-video into a production workspace with scene building, camera control, and asset reference. But u/MrBoondoggles offers a cooler take: “I'm not surprised Google is giving away Veo at this point... trying to maintain some interest in their product.”
- Thread 8, “Did Anyone Notice Sudden Quality Drop of Image Generation? From 2 MB to 500 KB” (r/GeminiAI, 10 points, 25 comments, 2026-09-17) https://www.reddit.com/r/GeminiAI/comments/1wj02p4/ — Users report quality degradation in closed-source Gemini output (PNG → JPEG, 8MB → 2MB → 500KB), including complaints from paid-plan users. u/Well_HellooF: “there's no difference in quality between the free version and the paid one. suck”
- Thread 5, “ArtPrize Allows Generative AI” (r/grandrapids, 354 points, 176 comments, 2026-09-16) https://www.reddit.com/r/grandrapids/comments/1wi4ub0/ — Strong backlash against an art competition accepting AI-generated works. u/Chirotera (319 points): “Fucking disgusting. It is not AI "Art," it's fucking theft.” General-community anger is greater than in technical subreddits.
- Thread 10, “Company expects us to generate 500 AI images PER WEEK. Is this realistic?” (r/graphic_design, 63 points, 133 comments, 2026-09-17) https://www.reddit.com/r/graphic_design/comments/1wieke2/ — A working designer laments a mass-production quota using a closed-source tool (ChatGPT). u/Diligent-Educator409 (123 points): “500 AI images? Yes. 500 good AI images? No. 1 good AI image? Also no.”
- Thread 9, “best apps for generating AI videos” (r/aitubers, 0 points, 46 comments, 2026-09-14) https://www.reddit.com/r/aitubers/comments/1wg3duk/ — There is demand for closed-source tools that automatically turn scripts into videos (InVideo AI, Steve AI, etc.), but the community response is cold. u/RobJames007 (15 points): “Youtube is trying to reduce AI slop, not allow more of it onto the platform.”
- Thread 3, “Please help me generate free ai video without subscription” (r/aivideomaking, 0 points, 20 comments, 2026-09-15) https://www.reddit.com/r/aivideomaking/comments/1wh80z3/ — u/Chance-Business says, “google flow you get 50 free credits per day, each vid is 6-12 credits,” while u/Bastisheen92 says, “Local Generation is free if you already own the Hardware,” reproducing the familiar contrast between closed-source free tiers and local open-source generation.
- Thread 11, “Are all of you also anxious about recent news about AI?” (r/AIToolTalks, 12 points, 36 comments, 2026-09-13) https://www.reddit.com/r/AIToolTalks/comments/1wfhbnv/ — Not directly about image or video generation, but discusses anxiety about AI’s water consumption, job losses, and regulation. Comments are sharply divided: u/Big-Pops78 downplays water concerns, while u/UnburyingBeetle counters with sarcasm about the phrase “cost efficiency.”
Signals
- Rising: Names of open-source/local models—Wan, MiniMax H3, LTX Video, and Krea2—appear repeatedly in independent threads (1, 2, and 12) in the same context: alternatives once closed-source free tiers have run out. Local generation is becoming shorthand for “free, high quality.”
- Dismissed or mocked: There is substantial sarcasm toward video-generation services that advertise themselves as “free.” In multiple threads (1, 4, 6, and 12), bot account u/Jenna_AI posts similar lengthy sarcastic comments about services claiming to be free but ultimately pushing users to pay. It symbolizes the community’s cynical mood.
- Surprising point: General communities (r/grandrapids, 354 points and 176 comments) and work-focused communities (r/graphic_design, 63 points and 133 comments) have higher engagement and scores than technical AI subreddits (r/generativeAI and others, mostly single-digit to low-double-digit scores). Backlash and discussion become much stronger when AI-generated content affects everyday life or work.
- Conflicting views: Thread 2’s GPT Image 2.5 Flare is rated in completely opposite ways: “incredible upgrade” by u/oldboi777, versus “the same result as Krea2” by u/SeaworthinessFresh16. Thread 7 similarly includes both positive views that Google Flow/Veo’s “free credits are generous” and negative views that “it's weak at physics and logic. Even Minimax is far better” (u/Sea-Temporary-6995).
Limits
- Only 12 threads were collected, short of the brief’s completion criterion of roughly 20 analyzed posts per platform. The 12 worker-collected items are all the Reddit data available for this stage, and Reddit cannot be searched or browsed further in this stage under the playbook.
- The only search term used was the English phrase “Image and Video Generation AI News.” There is no indication that Japanese queries or perspective-specific terms such as “open source” or “closed source” were attempted.
- Some subreddits, including r/aitubers, r/aivideomaking, and r/AIToolTalks, contributed only one thread each, so the strength of trends within those communities cannot be assessed.
X
X — Image and Video Generation AI (Closed/Open Source) News
Accounts
The 39 accounts and 40 posts collected in output/x.posts.md are all unrelated to image/video generation AI. The search terms were “Greenland,” “Denmark,” “#Bitcoin,” “NATO,” “Christ,” “Jubjub,” “Charles,” “Bosnia,” “Chelsea,” and “Belgrade.” These were general trend terms taken directly from X’s Explore trends, geolocated around the server connection source near Croatia. Not one term is tied to the research brief on image and video generation AI.
Therefore, the available data contains no accounts that can answer who is driving this topic on X. What was collected instead was:
- Politics/geopolitics cluster: @RapidResponse47 (30,291 likes, Greenland-related), @AJENews, @Rusia_HD, @Globalsurv, @NepCorres, and others posting news or opinions on Greenland, Denmark, and NATO.
- Cryptocurrency cluster: @aacryptoverse, @Bitcoin_Pirate_, @StackandRun, @bitcr_org, and others posting with the #Bitcoin tag, each with only single-digit to tens of likes.
- Royal-gossip cluster: @barristerlawusa, @hernandez_64876, @thebluestshade, @Rimmesfk, discussing a Charles Spencer exposé.
- Soccer cluster: @icunga_, @john322226, @Cfc_Kemboi, @Pats_Aura, where “Chelsea” refers to Chelsea FC match results.
- Meme/chat cluster: @SardineKing_O, @isellbeforeyou, @0xHeatt, discussing the “$jubjub” meme coin, plus two Serbian-language chat posts from @MarquiseDeBelgr.
Each account contributed only one or two posts, with no standout repeat poster. One @RapidResponse47 post (30,000 likes and approximately 6.8 million views) stands out in the set, but concerns Greenland’s political status and is unrelated to this topic.
Posts
Of the 40 collected posts, zero mention image/video generation AI, whether closed or open source. Therefore, there is no representative post to present. For reference, here is just one highest-engagement post illustrating the nature of the collection, explicitly unrelated to the topic:
- @RapidResponse47 (off-topic, reference only) — 30,291 likes, 5,022 reposts, 1,164 replies, approximately 6,800,000 views, 2026-09-18. https://x.com/RapidResponse47/status/2101059494587285834 Found through a “Greenland” search. It is a political post about Greenland’s status and has nothing to do with AI-generated images or video.
Signals
- The X-stage data contains no mentions, discussions, or news concerning image/video generation AI, including Midjourney, Sora, Runway, Stable Diffusion, Flux, Wan, Kling, and similar tools. There is no material from which to judge whether anything is or is not gaining attention.
- The search terms used—Greenland, Denmark, #Bitcoin, NATO, Christ, Jubjub, Charles, Bosnia, Chelsea, and Belgrade—exactly match headings from X’s own Explore list at the start of
output/x.posts.md. It appears the stage merely searched global trends from the connection region around Croatia: geopolitics, royal gossip, soccer, and cryptocurrency memes. Topic-relevant terms such as image generation AI, video generation AI, Sora, Midjourney, Stable Diffusion, or open-source AI were never used. - As a result, this stage yields not a single insight on either closed-source or open-source developments.
Limits
- The collection itself did not match the topic. The 10 search terms in
output/x.posts.mdall concern unrelated Explore trends: geopolitics, royal gossip, soccer, or cryptocurrency memes. Because the worker never searched for the topic—closed/open-source image and video generation AI—the X stage did not meet its completion criterion of analyzing roughly 20 topic-relevant posts. - Forty posts were analyzed, but none mentioned image or video generation AI.
output/x.posts.jsoncontains the same data and offered no additional clues.- The only valid conclusion for this X stage is that the collected queries and posts cannot support reporting any closed-source or open-source image/video generation AI trends from X. A topic-focused recollection is required, for example using “Sora 2,” “Midjourney,” “Stable Diffusion,” “Runway Gen,” “Kling AI,” “Flux,” or “open source image generation.”
YouTube
YouTube — Latest Trends in Image and Video Generation AI (Closed/Open Source)
Channels
Closed-source leaning
- Theo - t3.gg (@t3dotgg) — Technical breakdowns of Google Nano Banana Pro
- Astrovah (@astrovah) — Sora 2 reviews and use cases
- Woollyfern (@woollyferncreative) — Channel specializing in monthly Midjourney updates
- FixNode (@Fixnode1) — Runway Gen-4.5 tutorials
- Higher E-Learning (@higherelearning) — Testing models integrated into Adobe Firefly
- AIPOD-CAST (@AIPOD-CAST) — Weekly AI news roundup, episodes in the 220 range
- Lev Selector (@lev-selector) — Weekly AI update roundups
Open-source leaning
- Bijan Bowen (@Bijanbowen) — Local testing of Qwen Image
- HitPaw Edimakor (@HitPawEdimakorOfficial) — Reviews and tutorials for the Wan series
- MaxonShire (@MaxonShire) — Comparative testing of open-source video models
- Promptus AI (@promptusai) — Local setup guides for new models such as Z-Image
- 黎黎原上啃 / SweetValberry (@SweetValberry) — Chinese-language explainers on FLUX.1 Kontext and related models
Subscriber counts could not be obtained from any channel page (see Limits below), so channel scale could not be verified.
Videos
-
“Google won image generation (it's not even close) NANO BANANA PRO BREAKDOWN” — Theo - t3.gg / date unknown (Nano Banana Pro itself was announced November 20, 2025; the video is later) / views unknown
https://www.youtube.com/watch?v=UV9GqinedQ8
Argues that image quality from Gemini 3 Pro-based Nano Banana Pro is at a “no Photoshop needed” level, putting it clearly ahead even among closed-source competitors. -
“Sora 2 - An Honest Review As Well As 20 Creative Use Cases To Try” — Astrovah / October 7, 2025 / views unknown
https://www.youtube.com/watch?v=pJHWIgri5vk
Rates Sora 2 as “the most realistic AI video yet” and presents 20 practical use cases. -
“Midjourney Update | July 2026: V8.2 is HERE! Personalization, NIJI Style Creator, and More!” — Woollyfern / July 2026 / views unknown
https://www.youtube.com/watch?v=dvfH5HzCARY
Explains that Midjourney V8.2 adds personalization and a style creator for NIJI. The latest installment in a monthly series. -
“I Tested Every AI Video Model in Adobe Firefly So You Don't Have To (July 2026)” — Higher E-Learning / July 2026 / views unknown
https://www.youtube.com/watch?v=nOSYufWVdq8
Tests models side by side after Adobe Firefly integrated Veo 3.1, Kling 3.0, Runway Gen-4.5, and Sora 2. -
“Ultimate Runway Gen 4.5 Tutorial For New Users in 2026” — FixNode / March 29, 2026 / views unknown
https://www.youtube.com/watch?v=IUge3u4ZrqQ
Explains Runway Gen-4.5 image-to-video generation in tutorial form, emphasizing cinematic texture. -
“Episode 222: Weekly AI News Summary - 6 September 2026” — AIPOD-CAST / September 6, 2026 / views unknown
https://www.youtube.com/watch?v=8f34nSLdNtk
A weekly roundup spanning models, agents, and business developments that also mentions image/video generation AI news. -
“Exciting AI Updates Weekly - September 18, 2026” — Lev Selector / September 18, 2026 / views unknown
https://www.youtube.com/watch?v=Utu4zIcqPtM
An individual channel’s rapid roundup of AI updates from the previous week. The newest post in this research set. -
“Qwen Image-2512 First Test – The BEST Open Source Image Model!” — Bijan Bowen / date unknown (the model itself is a December 2025 version) / views unknown
https://www.youtube.com/watch?v=SBaK616nP6Q
Tests Alibaba’s Qwen-Image-2512 (20 billion parameters) locally and rates it “the strongest open-source image model currently available.” -
“Wan 2.6 Review | How to Use Wan 2.6 for Free | New AI Video Generator Tutorial” — HitPaw Edimakor / date unknown (model released December 2025) / views unknown
https://www.youtube.com/watch?v=6FMisTHYYgA
Reviews Alibaba Wan 2.6 and explains how to use it for free, covering multiple modes including T2V, I2V, and R2V. -
“HunyuanVideo 1.5 vs Wan 2.7 Comparison: Which is The Best Free Local Video AI Generation Model?” — MaxonShire / June 25, 2026 / views unknown
https://www.youtube.com/watch?v=4GNT4-QYekg
Directly compares two major free local video models: Tencent HunyuanVideo 1.5 and Alibaba Wan 2.7, released April 22, 2026. -
“Z-Image Open-Source Image Generator: Free Online and Local Setup” — Promptus AI / 2026, exact date unknown / views unknown
https://www.youtube.com/watch?v=JF4Q5hXh-_Q
Presents Alibaba’s Z-Image (6 billion parameters, S3-DiT architecture) as lightweight yet capable of surpassing Flux 2 and Qwen Image in quality, and explains ComfyUI integration. -
“FLUX.1 Kontext [dev] is open source! Try image editing locally in ComfyUI” — 黎黎原上啃 / 2025, shortly after Flux Kontext Dev weights were released / views unknown
https://www.youtube.com/watch?v=v4pp3TdbWNw
Demonstrates local image editing in ComfyUI following the release of Black Forest Labs’ Flux Kontext Dev model weights. Slightly older, but included for context as a starting point in the lineage of open-source image editing.
Signals
- Closed-source players have made monthly updates routine: Woollyfern’s Midjourney “Update” series posts monthly update videos, with steady progression from V8 to V8.1 to V8.2 in 2026. Tech channels immediately review similarly substantial updates to Runway and Adobe Firefly every few months.
- Synchronized audio is becoming a standard feature of closed-source video generation: Multiple search results emphasize generating sound and imagery together—Kling 3.0 with native dialogue in five languages, Seedance 2.0 with an integrated audio-video architecture that reproduces even reverberation, and Grok Imagine 1.5 with simultaneous dialogue and ambient sound. Competition is shifting from isolated visual clips to generating short films with audio.
- Open-source players, especially those from China, are releasing at a pace equal to or faster than closed-source competitors: Within Alibaba alone, Qwen-Image → Qwen-Image-2512 → Z-Image and Wan 2.5 → 2.6 → 2.7 continued to update over short intervals. Tencent HunyuanVideo 1.5 and Lightricks LTX-2 → 2.3 → 2.5 are also advancing at near-monthly or quarterly pace. Video titles frequently use hype language such as “the strongest open source” or “defeats X,” suggesting strong viewer interest.
- Most open-source video coverage emphasizes “ComfyUI,” “local execution,” and “free”: Channels such as HitPaw Edimakor, Promptus AI, and MaxonShire foreground how to use models for free and on local GPUs. This contrasts with closed-source channels such as Theo, Astrovah, and Woollyfern, which lean toward reviews of quality and features.
- Weekly AI-news channels such as AIPOD-CAST and Lev Selector have made image/video generation AI a recurring segment, treating it as an ongoing watch category rather than a one-off news topic.
Limits
- YouTube search results (
https://www.youtube.com/results?search_query=…) are rendered dynamically with JavaScript. When retrieved with WebFetch, only footer navigation links were available, so the playbook’s intended method—reading titles, channels, view counts, and posting dates from page HTML—did not work. - As an alternative, videos were discovered through ordinary web search using
site:youtube.comqueries, then titles and channel names were verified using YouTube’soembedendpoint. This method could retrieve neither view counts nor subscriber counts, so all videos above list views as unknown; no estimates were invented. - For the same reason, precise posting dates could not be confirmed for several videos, including the Nano Banana Pro breakdown, Qwen Image-2512 test, Wan 2.6 review, and Z-Image introduction. Only broad timing based on search snippets and related model release dates is listed.
- Video descriptions and top comments could not be read directly for the same JavaScript-dependency reason.
- Posts within 60 days, from July 22, 2026 onward, were prioritized. However, one or two out-of-period videos—such as the Flux Kontext and Runway Gen-4.5 tutorial videos—were included for context needed to understand their respective open- and closed-source lineages.
Bluesky
Bluesky — Latest Trends in Image and Video Generation AI
Accounts
- Simon Willison (@simonwillison.net) — Independent AI researcher. Whenever a new multimodal model appears, he tests its image-generation capabilities with his own “pelican riding a bicycle” benchmark. Around 50,000 followers and highly active.
- Max Woolf (@minimaxir.bsky.social) — Former BuzzFeed data scientist with expertise in AI-content ethics and R&D. Often posts reactions to image-generation model releases.
- Ethan Mollick (@emollick.bsky.social) — Wharton professor. Covers general AI trends, including changes in AI-video quality.
- Replicate (@replicate.com) — Official account for a model-hosting service. Announces new closed-source image and video models as they become available on its platform.
- Stability AI (@stabilityai.bsky.social) — Official account of Stable Diffusion’s developer. Recent posts focus on Stable Audio and enterprise image-editing APIs, and posting stopped after November 19, 2025.
- Stable Diffusion online AI (@stablediffusion.bsky.social) — An account sharing SDXL/ComfyUI prompts and AI art, with around 1,800 followers. It has not posted since February 24, 2025.
- AI Art News (@ai-art-news.bsky.social) — A curation account for AI-art news. No posts since September 18, 2025.
Posts
-
Simon Willison (2026-09-19) — In a thread about having GPT-6 Astra and Claude Fable 5.1 generate Blender 3D models using map data, introduces an image-generation-to-3D workflow. 57 likes, 5 reposts.
https://bsky.app/profile/simonwillison.net/post/3mv4su6pfzk24 -
Simon Willison (2026-09-05) — Tests GPT-6 Astra by having it render a pelican riding a bicycle in Blender. 405 likes, 30 reposts.
https://bsky.app/profile/simonwillison.net/post/3murtmdynq22s -
Simon Willison (2026-09-04) — A comparison grid using the “pelican riding a bicycle” image-generation benchmark across GPT-6 Astra and GPT-5.6 Sol/Terra/Luna. 206 likes, 9 reposts.
https://bsky.app/profile/simonwillison.net/post/3mupxubgrls2c -
Simon Willison (2026-09-02) — Generates the highest-quality SVG pelican image so far with Claude Fable 5.1 at Max thinking level ($3.30 per run), then animates it. 362 likes, 22 reposts.
https://bsky.app/profile/simonwillison.net/post/3muimzxo2sk2g -
Max Woolf (2026-09-19) — Notes that when asked to generate a vector-style image of a pelican riding a bicycle, image-generation AI does not understand the relationship between legs and pedals. 1 like.
https://bsky.app/profile/minimaxir.bsky.social/post/3mvtt3uxdrk2c -
Max Woolf (2026-09-08) — Reacting to OpenAI’s new image-model announcement: “Good thing I delayed my ChatGPT Images 2.0 summary article; this looks more important,” referring to ChatGPT Images 2.5. 4 likes.
https://bsky.app/profile/minimaxir.bsky.social/post/3muzq6mcadk2n -
Ethan Mollick (2026-09-19) — Notes that amid a flood of low-quality mass-produced content (“slop”), genuinely interesting AI video work is beginning to emerge. 58 likes, 7 reposts.
https://bsky.app/profile/emollick.bsky.social/post/3mvuss476oc2b -
Replicate (2026-04-21) — Announces the addition of OpenAI’s GPT Image 2 to Replicate, highlighting photorealism, text rendering, and strong layout adherence. 5 likes.
https://bsky.app/profile/replicate.com/post/3mjzygaefs224 -
Replicate (2026-04-09) — Announces that ByteDance’s video model Seedance 2.0 is available to all users. It integrates text, images, video, and audio, with synchronized stereo audio and realistic physics. 2 likes, 1 repost.
https://bsky.app/profile/replicate.com/post/3mj3junhvnh26 -
Replicate (2026-02-18) — Announces Runway Gen-4.5, a cinematic video generator focused on physical accuracy and realism. 2 likes.
https://bsky.app/profile/replicate.com/post/3mf5fbf6u4l2c -
Replicate (2026-02-17) — Announces the addition of Kuaishou’s Kling 3.0 and Kling o3, supporting multi-shot 4K generation, synchronized audio, video editing, and style transfer. 2 likes.
https://bsky.app/profile/replicate.com/post/3mf35lkhoyw2q -
Replicate (2026-03-11) — Announces the addition of Shengshu’s Vidu Q3, supporting video generation up to 16 seconds and 1080p from text, images, and start/end frames, with synchronized audio. 1 like.
https://bsky.app/profile/replicate.com/post/3mgsan3ddpl2w
Signals
- Closed-source dominance: Nearly every relevant Bluesky post found concerned major closed-source models—OpenAI’s GPT Image 2 / ChatGPT Images 2.5, Runway Gen-4.5, Kling 3.0, Seedance 2.0, and Vidu Q3. These are not viral organic posts, but announcements from model-hosting companies such as Replicate or testing posts by individual researchers such as Simon Willison and Max Woolf.
- Open source is almost absent: No active accounts posting about Flux, Stable Diffusion, Qwen-Image, Wan, or ComfyUI workflows could be found. The only plausible community account, stablediffusion.bsky.social, stopped posting in February 2025. Stability AI’s official account has also been silent since November 2025, and its last posts focused on Stable Audio and enterprise APIs rather than Stable Diffusion image generation.
- “A pelican riding a bicycle” has become a de facto benchmark: Whenever new multimodal models such as GPT-6 Astra or Claude Fable 5.1 appear, several independent AI observers compare image quality using this same prompt. It is a Bluesky-specific in-joke that has become an informal shared measure of model ability.
- Official corporate accounts are absent: Expected accounts for major brands such as OpenAI, Midjourney, Runway ML, Black Forest Labs, Hugging Face, Civitai, and ComfyUI either did not exist or were unused accounts with zero posts. Bluesky is therefore not a primary-announcement channel for these companies; news reaches it through individual researchers and intermediary platforms such as Replicate.
- Changing assessments of video generation: As Ethan Mollick’s post suggests, there is growing recognition that genuinely high-quality work is starting to appear amid large volumes of formulaic AI video. This remains a general observation, however, rather than a reference to any particular open-source video model.
Limits
- Bluesky’s official search API (
https://public.api.bsky.app/xrpc/app.bsky.feed.searchPosts) consistently returned HTTP 403 Forbidden, even after varying keywords and trying two CORS proxies. The web UI athttps://bsky.app/search?q=...is also a client-side SPA, so WebFetch could not retrieve its contents. - As an alternative, the unauthenticated
app.bsky.actor.getProfileandapp.bsky.feed.getAuthorFeedendpoints were used to retrieve feeds for accounts discovered through web search or inference. The result is therefore not a keyword search across Bluesky as a whole, but is limited to posts from accounts that could be found. - Official accounts for key brands—OpenAI, Midjourney, Runway ML, Black Forest Labs, Hugging Face, Civitai, ComfyUI, and parts of Stability AI—were unused or silent, so direct news could not be collected from them.
- Because search was unavailable, the brief’s target of analyzing roughly 20 clearly relevant posts could not be met. More than 100 posts from seven accounts were reviewed, and 12 directly relevant ones were selected.
- Images and videos themselves were not displayed or verified; the source was post text only.
Lemmy
Lemmy — Latest Image and Video Generation AI Trends (Closed/Open Source)
Communities
- !«メールアドレス» — 5,712 subscribers, including 893 local subscribers; 1,407 posts and 1,927 comments. Covers open-weight image/video generation models broadly. Small in scale, with 10 daily active and 66 monthly active users, but actively updated.
- !«メールアドレス» — 2,362 subscribers; 24 daily, 114 weekly, and 344 monthly active users. A place to post works made with Stable Diffusion-style open-weight models, mostly direct links to civitai images.
- !«メールアドレス» (community name
share_anime_art, displayed as “Stable Diffusion Anime”) — 1,598 subscribers, including 206 local subscribers. An SFW-only community for anime-style AI-generated illustration. - !«メールアドレス» — 8,252 subscribers, including 3,027 local subscribers, and 9,179 monthly active users—one of the largest communities examined. It describes itself as “a place for all those who loathe AI” and centers on criticism and satire of AI generally rather than image/video generation specifically.
- !«メールアドレス» — 52 subscribers, so small in scale, but it mirrors Reddit threads such as r/ArtificialInteligence via RSS and frequently carries image/video generation AI topics. 725 users active over six months.
- !«メールアドレス»・!«メールアドレス»・!«メールアドレス» — General technology communities. Major Midjourney news appeared here.
Posts
- A sharp increase in ComfyUI tools for MiniMax-H3 (open source) — At least 15 MiniMax-H3 video-generation tool posts appeared in
!«メールアドレス»between 2026-09-01 and 09-16 alone. Representative examples:- “ComfyUI-MiniMaxH3-CLSS” — Generates arbitrary-length videos with audio on consumer 16GB VRAM (score 0, 2026-09-01) https://github.com/nazgut/ComfyUI-MiniMaxH3-CLSS
- “H3-World” — Claims to be the world’s first interactive world model based on MiniMax-H3 (score 3, 2026-09-02) https://huggingface.co/DANNY621/H3-World
- “ComfyUI-VDN-H3-24GB” — Hybrid-attention implementation for 24GB GPUs (score 6, 2026-09-12) https://github.com/Speach1sdef178/ComfyUI-VDN-H3-24GB
- “MiniMax-H3-Image-Training-Adapter” (Circlestone Labs, score 5, 2026-09-12) https://huggingface.co/circlestone-labs/MiniMax-H3-Image-Training-Adapter
- Boogu-Image-0.1 — A new open image foundation model from a Huawei-affiliated lab (open source) —
!«メールアドレス», score 5, 2026-06-17. Apache-2.0 licensed, 10 billion parameters, with five variants: Base, Turbo (3–4 steps), FP8, and editing variants. Its selling point is bilingual Chinese-English text rendering. https://boogu.org/ - Technical analysis of Seedream 5.0 Pro, a closed ByteDance-affiliated model (closed source) — via
!«メールアドレス», score 1, 2026-07-10. A testing post titled “an honest comparison and technical breakdown.” https://www.reddit.com/gallery/1usc03q - Google announces “Nano Banana 2 Lite” (closed source) — Hacker News mirror, score 1, 2026-06-30, linking to an official DeepMind page. A Swiss tech-media post in German was also circulating in parallel (score 0, swisstechnews, 2026-07-02). https://deepmind.google/models/gemini-image/flash-lite/
- Microsoft MAI-Image-2.5 approaches Nano Banana 2 in benchmarks (closed source) —
!«メールアドレス», score 1, 2026-05-28. Covers the Google-versus-Microsoft image-generation model race. https://www.reddit.com/r/ArtificialInteligence/comments/1tpu2cd/ - An experiment making a long-form story with Sora 2 (closed source) —
!«メールアドレス», score 1, 2026-09-13. The creator began about a month after Sora 2’s release and made seven one-hour videos. The key finding: producing beautiful individual clips is not especially difficult; what is truly difficult is “production memory,” or maintaining consistency. https://lemmy.durstig.online/post/59922 (original Reddit: https://www.reddit.com/r/ArtificialInteligence/comments/1wfabp9/) - The real news that Midjourney is boldly pivoting from AI image generation to medical spas (closed source/company development) —
!«メールアドレス»(The Register article, cross-posted on lemmy.zip, score 58–66, 2026-06-18). Reportedly pivoting to a full-body-scanning “Golden Light” spa business, borrowing core technology from a partner; comments were full of Theranos comparisons. https://lemmy.zip/post/66397234 - Midjourney asks Hollywood studios to disclose AI use (closed source) —
!«メールアドレス», score 73, 2026-07-05. Reported in connection with copyright litigation. https://lemmy.today/post/56011946 - Introduction to the InterleaveThinker paper (open source/research) —
!«メールアドレス», score 0, 2026-06-12. Link post to the arXiv paper “Reinforcing Agentic Interleaved Generation.” https://arxiv.org/abs/2606.13679 - The temperature of backlash against AI-generated content (social signal) —
!«メールアドレス», score 923, 2026-09-13. The post concerns AI-powered smart glasses (Ray-Ban Meta), not image/video generation directly, but the community’s scale (9,179 monthly active users) and strength of reaction are recorded as supporting evidence for the headwinds facing image/video AI debate. https://lemmy.world/post/51874921
Signals
- The open-source side is all about MiniMax-H3. In the first half of September alone,
!stable_diffusionon lemmy.dbzer0.com saw nearly daily posts about ComfyUI nodes, LoRAs, quantization, and VAE-acceleration tools for MiniMax-H3. Older model names such as Wan, Flux, and HunyuanVideo barely appeared in search results. The fact that primary posters are individual developers, often using personal GitHub accounts, also shows the grassroots nature of the Hugging Face/civitai-centered ecosystem. - On the closed-source side, five companies are moving in parallel: Google (Nano Banana), Microsoft (MAI-Image), ByteDance (Seedream), OpenAI (Sora 2), and Midjourney. Yet the number of Lemmy mentions itself is low, with scores mostly in single digits, and the main flow of discussion comes only through Reddit mirrors such as
!ai_reddit. Lemmy-originated discussion leans toward corporate news, such as Midjourney’s medical-spa pivot. - Artwork posts linking directly to civitai (stable_diffusion_art / share_anime_art) are active, but usually offer little detail about model names or prompts, making them source material rather than news.
- The anti-AI community
!fuck_aiis among Lemmy’s largest, and when image/video AI topics reach it, backlash comments tend to outweigh balanced debate.
Limits
- Lemmy has a small base, and its search API returns many old posts—such as HunyuanVideo-I2V from March 2025—and irrelevant matches, such as nuclear-fuel startup stories when searching “Flux.” Noise had to be manually removed keyword by keyword.
- Individual searches for
Runway Gen,Kling AI, andWan 2.5found no posts directly related to image/video generation AI: Kling returned zero results, Runway returned zero, and Wan returned only unrelated posts. No independent Lemmy activity around these models was observed. !«メールアドレス»is an RSS repost bot for Reddit, not an independent Lemmy discussion venue. The report notes its source and uses only distinct insights to avoid duplicating the Reddit stage.- News about Midjourney’s medical-spa pivot and Hollywood disclosure demands was posted on 2026-06-18 and 2026-07-05, respectively, rather than within the most recent week. No newer follow-up was found on Lemmy.
- Roughly 20 posts were reviewed, but only the Midjourney medical-spa story and the
!fuck_aismart-glasses post reached double-digit scores. No major viral discussion focused solely on image/video generation AI was observed across Lemmy communities in this run.
Pinterest — Image and Video Generation AI News
Thirty of the 50 collected pins were opened and read directly (all with Read, images included) to write this summary; the remaining 20 titles (mostly generic “AI content creation concept” stock-photo listings and duplicate tool-roundup graphics) were not opened because their titles already match themes confirmed below.
Visual themes
- The “AI news” YouTube-thumbnail template dominates: black/navy background, a human face reacting (shocked eyebrows or laughing), bold white/red “AI NEWS” text, and a row of glowing brand-logo badges (OpenAI, Google, Anthropic-orange, Meta, Microsoft, Notion). Seen repeatedly across unrelated topics, sometimes with a title that doesn’t match the pictured content — the image is a reusable channel template, not bespoke art.
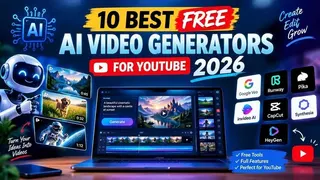
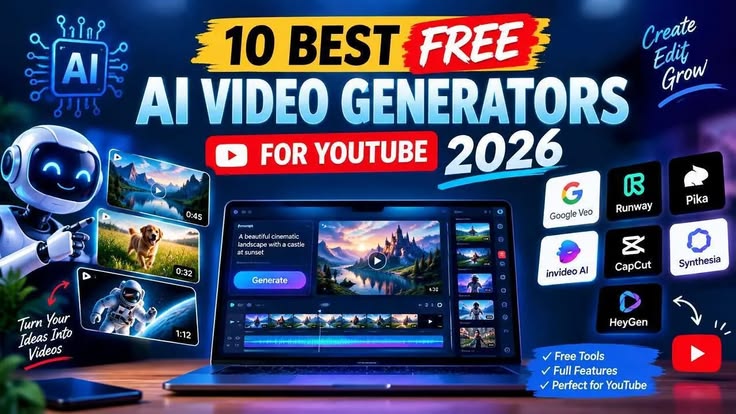
[6, 14, 41, 43, 47] - Tool-roundup listicles use the same dark-neon infographic language: numbered badges (purple/orange/teal), a laptop mockup with a generation UI, and a grid of competing app logos — Runway, Pika, Kling AI, Luma/Dream Machine, Canva, Hailuo, invideo AI, CapCut, Synthesia, HeyGen. Every tool named is closed-source SaaS.
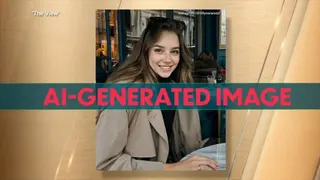
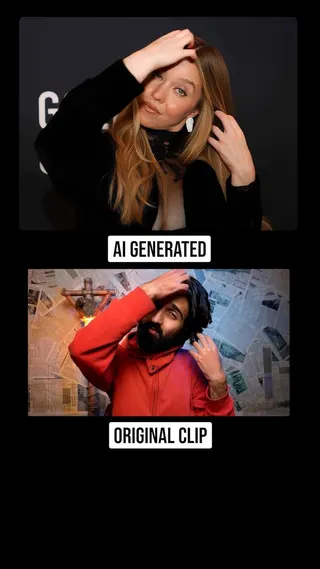
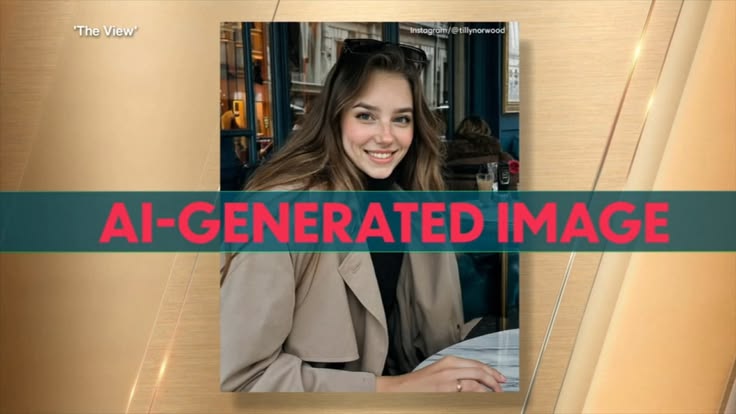
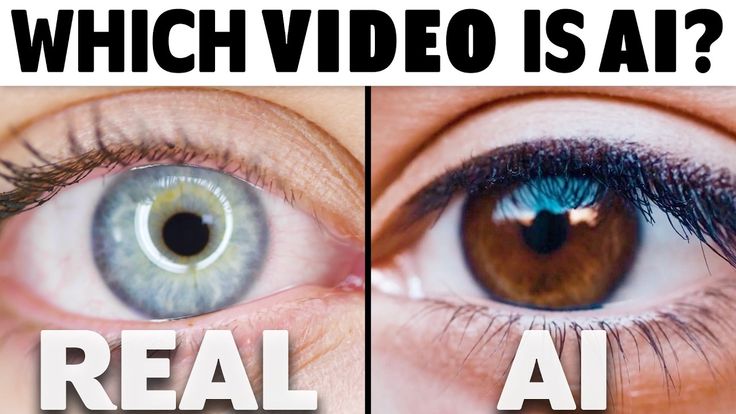
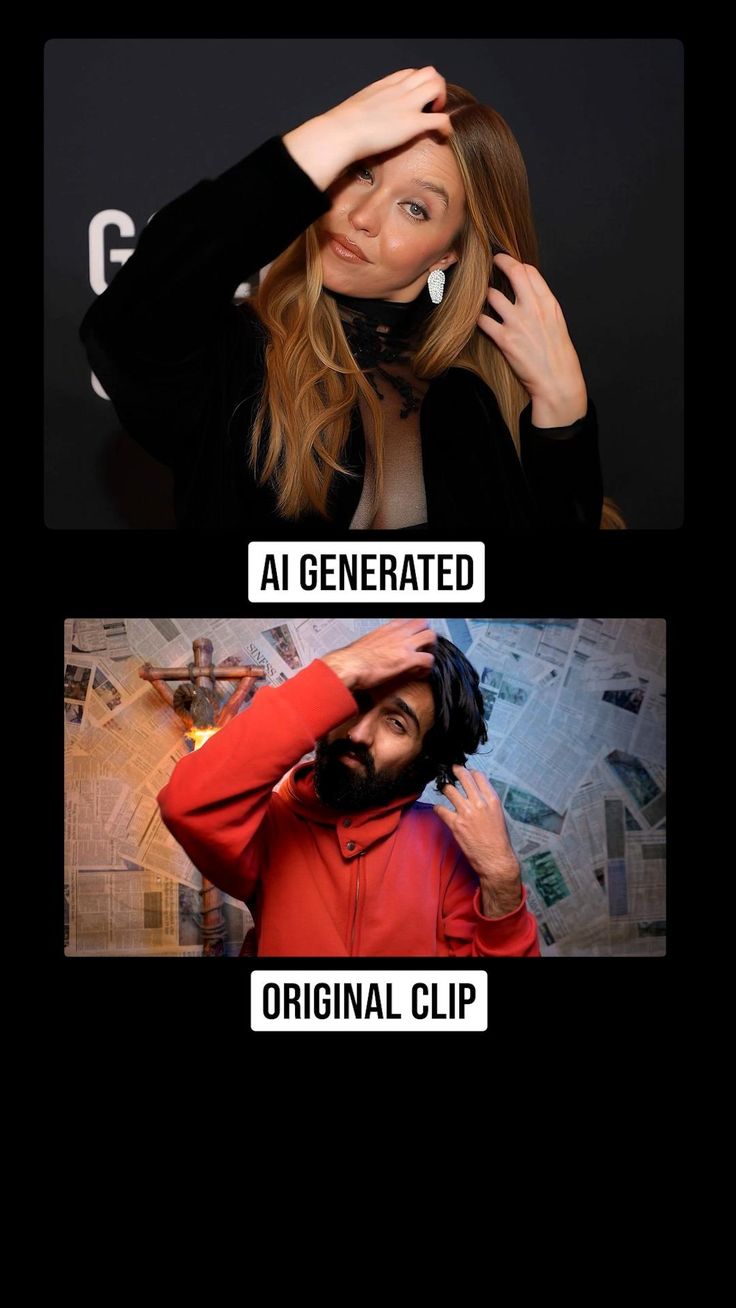
[2, 29] - “Real vs AI” authenticity-anxiety is a distinct recurring format: side-by-side quizzes (“Which is AI?”), red-banner “AI-GENERATED” labels stamped over a photo, and meme-style “AI GENERATED / ORIGINAL CLIP” comparisons. This is as common a genre as the news thumbnails themselves.
[3, 21, 32] - Google’s Veo supplies the default “cinematic AI video” visual vocabulary: the same warm Pixar-style stills (a girl in a kitchen, flamingos, a dancer under stars, a swimmer, a scientist at a microscope) recur across multiple separate pins, plus a distinct plush-monster image-to-video demo for Veo 3. No competitor’s demo reel appears this often.
[8, 9, 13, 27] - Hyperreal AI portraits are used as generic bait art, regardless of the article’s actual subject — a wrinkled fisherman’s face for a tool announcement, a glitter-skinned woman’s profile for a news-roundup card, a face-morph triptych for a novelty app. Skin pores, catchlights and shallow depth of field are the tell that these are themselves AI-generated.
[33, 45, 48, 20] - Generic sci-fi/circuit-board stock imagery fills gaps where no real product screenshot exists: glowing wireframe brains, a chrome humanoid robot, a suited businessman facing a holographic AI dashboard. These carry no news value, just mood.
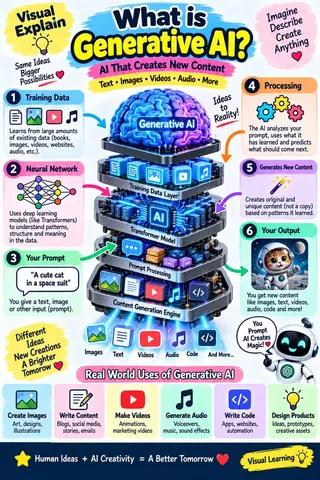
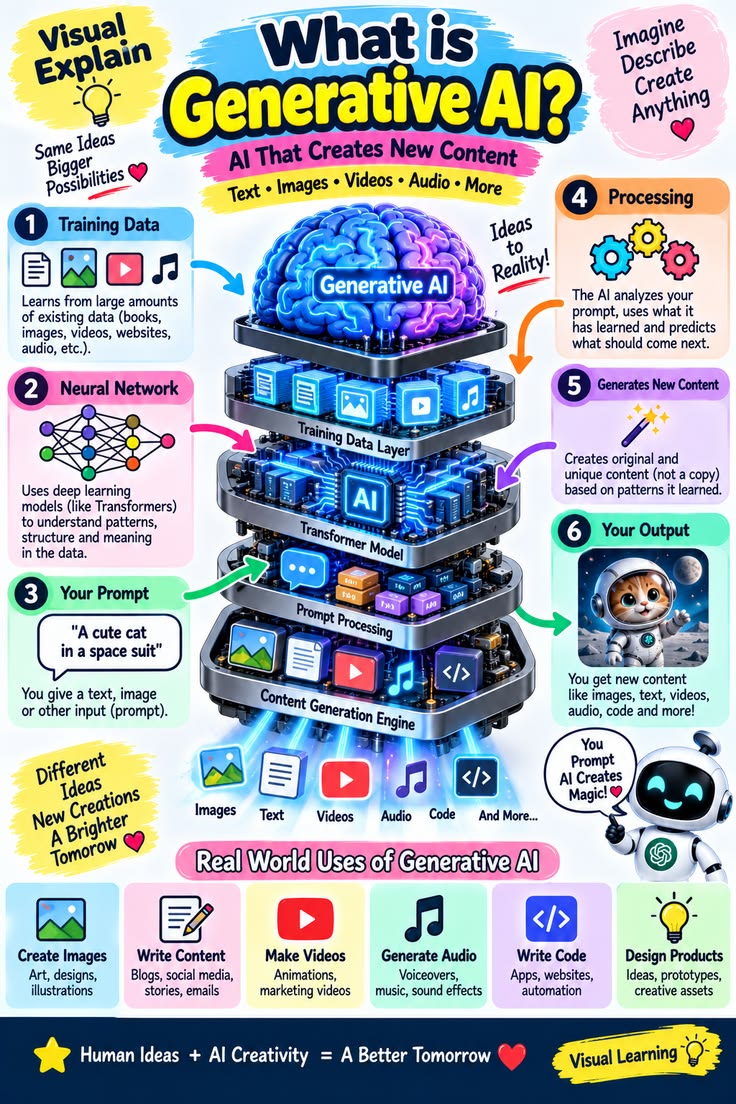
[1, 37, 50] - Beginner-facing educational infographics use a pastel, cartoon register (yellow/pink, a smiling robot mascot, hand-drawn arrows) — a visibly different, softer style from the news-thumbnail genre, aimed at people who don’t know what “generative AI” means yet.
[7] - Genuine technical diagrams are rare: only one pin in the sample showed an actual model-architecture figure (text embedding → diffusion → upscaling stages), and even that was dressed up as a glossy magazine graphic rather than a research illustration.
[34]
Notable pins
- #48 — “Amuse 3.0”, an AI art creation tool (pin) — an AMD-branded, locally-run image generator shown via a hyperreal portrait; the only clearly local/open-adjacent tool surfaced in this sample, against a sea of closed SaaS listicles.
- #27 — Google announces video generation AI ‘Veo 3’ (pin) — shows an input still of a plush monster and three generated output videos in different scenes, i.e. Veo 3’s image-to-video consistency as the actual selling point.
- #46 — ByteDance and Hollywood reach global deal on AI copyright (pin) — a Cointelegraph-style news card reporting a ByteDance–MPA IP agreement covering its image/video tools, illustrated with a Pixar-style generated boy.
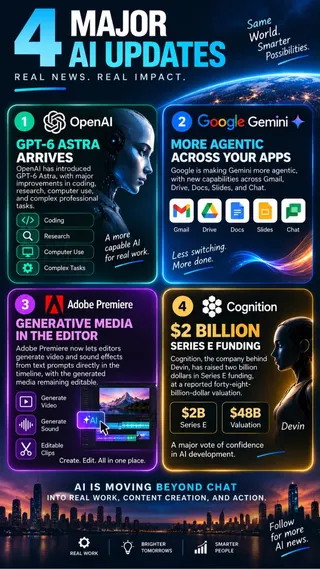
- #10 — “4 Major AI Updates” (pin) — names GPT-6 Astra, a more agentic Gemini, generative media inside Adobe Premiere, and Cognition’s $2B Series E ($48B valuation) in one infographic.
- #49 — “Today’s AI News, May 20 2026” (pin) — Google I/O recap: Gemini 3.5 Flash, Gemini Omni, Gemini Spark, and an AI smart-glasses push.
- #3 — Hollywood Reporter interviews the first AI actress (pin) — a TV chyron about “Tilly Norwood,” an AI-generated actress, with the frame itself stamped “AI-GENERATED IMAGE.”
- #41 — “More than 20% of YouTube is now AI-generated” (pin) — a bare stat-headline pin with no supporting chart, cited as fact.
- #29 — “10 Best Free AI Video Generators for YouTube 2026” (pin) — the widest single tool roundup in the sample: Google Veo, Runway, Pika, invideo AI, CapCut, Synthesia, HeyGen, all positioned as free/YouTube-ready.
- #34 — OpenAI’s Secret Image Generation Tool to Debut Soon (pin) — headline about a closed-source unreleased tool, illustrated with a genuine (if magazine-ified) diffusion-pipeline diagram rather than a product shot.
- #32 — an “AI GENERATED” vs “ORIGINAL CLIP” comparison meme (pin) — a face/gesture recreated by AI next to the real source clip, part of the platform’s ongoing authenticity-spotting genre.
Signals
- Current: Google Veo (2 and 3) is the single most visually repeated video model on the board — more than any other named tool. “AI is moving beyond chat into real work” is an explicit framing in more than one pin (Adobe Premiere generative timelines, Cognition’s Devin funding, Gemini going agentic across Gmail/Drive/Docs). IP and copyright deals (ByteDance × MPA) are now mainstream-news material, not just a niche legal story. The “spot the AI” / authenticity-labeling format is a genre in its own right, suggesting real audience anxiety about fake images and actors (Tilly Norwood). Reused generic thumbnails (the same face-and-logos template recurring under different headlines) suggest a lot of this “news” content is low-effort content-mill output rather than original reporting.
- Absent: open-source model culture is almost invisible — no Stable Diffusion, Flux, ComfyUI, LoRA, or GitHub-repo screenshots turned up; Amuse 3.0 (#48) was the only local/open-adjacent tool in the sample, and even it was framed as a polished consumer app rather than an open-source project. No non-English-language pins surfaced. Nothing in the sample plays as video — everything is a static thumbnail, so actual model output quality can’t be judged from the images alone, only claimed.
Limits
- Per the playbook, Pinterest was not browsed directly; this summary is built entirely from the worker’s pre-collected
output/pinterest.pins.mdtable andimages/pinterest/manifest.json/images, all from a single unnamed query (“Image and Video Generation AI News”) rather than a genre-by-genre breakdown — the manifest’sgenrefield is empty for every pin, so no genre-by-genre comparison could be written. - Thirty of the 50 collected pins were opened; the other 20 were skipped because their titles duplicate formats already covered (generic “AI content creation concept” stock-photo listings, repeat tool-roundup graphics) — a spot check, not full coverage of the set.
- Several pin titles are blank (“(untitled)”) in the source table; where that happened, the description above is based on text visible inside the image itself.
- A few pins’ pictured content does not literally match their title (for example, #47’s image is a generic “AI NEWS” channel card, not anything specific to Grok 5). This supports the “reused generic thumbnail” finding above, but means titles should be read as directional rather than confirmed reporting.
- No pin carried a visible publication date; the freshness of news claims, such as the claim that 20% of YouTube is AI-generated, could not be verified from the image alone.
Recommended actions
- Recollect the X stage with directly relevant search terms such as ‘Sora 2’ ‘Midjourney’ ‘Stable Diffusion’ ‘Runway Gen’ ‘Kling AI’ and ‘open source image generation’.
- Continuously monitor release frequency from China-originated open-source players including MiniMax-H3, Qwen, Wan, and Z-Image.
- Track reactions in general and professional communities as well as AI-specialist communities, and monitor the spread of backlash against AI-generated content.
- Test alternative access methods that resolve Bluesky official search API’s 403 issue.
- Follow developments around Sora 2’s “production memory” problem and Midjourney’s medical-spa pivot in the next run.
- Add genre tags to Pinterest collection so open and closed source can be classified mechanically.
Collected images























Data quality notes
Because X used search terms unrelated to the topic, zero of its 40 items were usable. Reddit (12 items) and Bluesky (roughly 12 items gathered through individual accounts due to the blocked search API) also fell short of the target of about 20. Pinterest relies on pre-collected data without genre tags, and YouTube view and subscriber counts could not be retrieved.