Image and Video Generation AI News — 2026-10-02
Chinese open-source models (Qwen-Image-2.1, Z-Image Turbo) are closing in on closed-source leaders just as closed-source trust erodes over guardrails, misuse, and Sora's economics.
Chinese open-source models (Qwen-Image-2.1, Z-Image Turbo) are closing in on closed-source leaders just as closed-source trust erodes over guardrails, misuse, and Sora's economics.
Image and Video Generation AI News — 2026-10-02
Honestly, the image and video generation AI space is getting wild right now 😤 Closed-source players (OpenAI's GPT Image 2.5, Google's Veo 3.1/Nano Banana 2.0, Kling 2.5, Seedance 2.5, and others) are locked in an unstoppable feature race, but at the same time there are mounting trust issues around stronger guardrails, deepfakes, and Sora's massive losses 💸. Meanwhile, Chinese open-source players such as Alibaba (Qwen-Image-2.1 and Z-Image Turbo) are gaining serious momentum, and a culture of heavily experimenting locally with ComfyUI at the center is visible across Reddit, Lemmy, and Bluesky 🔥. This time, I looked at six platforms—Reddit, X, YouTube, Bluesky, Lemmy, and Pinterest—but X was a complete miss, so I’ll report that honestly below 👇.
Across platforms
- Chinese open source is on the rise, and it is increasingly framed as a “closed-source alternative” 🇨🇳 On YouTube, Z-Image Turbo (6B parameters, runs on 6GB VRAM) is said to outperform Flux 2 (https://www.youtube.com/watch?v=JF4Q5hXh-_Q), while Qwen-Image-Edit is rated as comparable to or better than Nano Banana (https://www.youtube.com/watch?v=AIgYj5RG-FQ). Lemmy saw a cluster of WebUIs and LoRAs around Qwen-Image-2.1 released in the same week (https://github.com/ogoun/fooocus-qwen-image-2.1), and Simon Willison is testing Qwen-Image hands-on on Bluesky (https://bsky.app/profile/simonwillison.net/post/3lvlvsxkzp223). Since this is happening across multiple platforms at once, it feels like a real shift.
- Stronger guardrails are driving users away 🚪 On Reddit, some users are leaving ChatGPT over refusals for Midjourney, Grok, and Venice AI (https://www.reddit.com/r/AI_Agents/comments/1wt7jqr/), while tougher DreamFort.ai filters are pushing others toward Seedream Unfiltered and MiniMax H3 (https://www.reddit.com/r/generativeAI/comments/1wtzefv/). On Bluesky, experts are warning that open-weight models such as GLM-5.3 have virtually no guardrails (https://bsky.app/profile/emollick.bsky.social/post/3mu5xtm24zk2o). The split between tighter regulation and an anything-goes environment is visible across social platforms.
- Trust in closed-source tools is being shaken from several directions at once ⚠️ A TIME investigation shared on Bluesky found that Veo3 could create fake videos of a Hindu temple burning (https://bsky.app/profile/amanbatheja.bsky.social/post/3lqpalskjp22h). On Reddit, Photoshop and Apple Photos were reportedly labeling even ordinary crops as “AI-edited” and stripping credit information (https://www.reddit.com/r/mildlyinfuriating/comments/1wsupkx/). Misuse and incorrect labeling are different problems, but both feed into the feeling that closed tools cannot be trusted.
- ComfyUI is firmly the default workspace for the open-source crowd 🛠️ The same name comes up everywhere: Reddit (a MiniMax-H3 node, https://www.reddit.com/r/StableDiffusion/comments/1wtu82e/), Lemmy (LanPaint inpainting, https://github.com/scraed/LanPaint/), Bluesky (daily illustrations with Krea2, https://bsky.app/profile/ria-tatibana.bsky.social/post/3mwtrqf7glc2t), and YouTube, where setup tutorials appear immediately for every new model.
- Side-by-side comparisons have become a staple content format 📊 YouTube titles like “WAN 2.5 is Open Source Veo3,” Lemmy posts comparing the same Berserk spread colored by four models (https://www.reddit.com/gallery/1wfyqdy), and Pinterest neon comparison charts saying “pick this if you pay, pick this if you want free.” People are more interested in which model is strongest than in standalone news.
- Multiple sources support the idea that consumer AI video is not profitable 💰 A Bluesky post puts Sora2’s annual operating cost at roughly $5 billion versus about $1.4 million in revenue (https://bsky.app/profile/labuzamovies.com/post/3mek2c2xipk2o). Lemmy analysis says OpenAI shut down the Sora API on September 24 while enterprise-focused companies such as Kling are raising money (https://www.reddit.com/r/ArtificialInteligence/comments/1wluu0n/).
Platform by platform
Reddit 🟠 12 threads across 9 subreddits were analyzed. The biggest closed-source story was that Seedance 2.5 (via Higgsfield) has reached the point where one person can make a 10-minute short with consistent characters (784 points, https://www.reddit.com/r/accelerate/comments/1wqqr4p/). On the open side, a ComfyUI node for MiniMax-H3 was praised as “the best node I’ve ever used” (https://www.reddit.com/r/StableDiffusion/comments/1wtu82e/). This was also where complaints about guardrails were most concrete.
X ⚫️ This was genuinely a complete miss 😅 All 40 collected posts (from 33 accounts) were about soccer, K-pop, UK politics, or reality TV, with zero discussion of AI image or video generation. The worker’s search terms were simply X trending-tab terms such as “Halloween,” “Ronaldo,” and “#bb28,” rather than AI-related queries. So there is no useful information from X for this report.
YouTube 🔴 On the closed side, videos covering GPT Image 2.5’s “Sketch” feature (https://www.youtube.com/watch?v=LYUr4BY33h4), Veo 3.1 becoming free (https://www.youtube.com/watch?v=uj6eD31OxkA), and Nano Banana 2.0 as “better than Photoshop” (https://www.youtube.com/watch?v=u22-XoQvI4I) all appeared around the same time, showing how fast the feature race is moving. On the open side, FLUX.2, Z-Image, and Qwen-Image-Edit tutorials are being produced at scale in the format of “how to run this in ComfyUI.” Note, however, that view counts, subscribers, and comments could not be retrieved because of JavaScript rendering, so this analysis is based only on titles and oEmbed data.
Bluesky 🔵 More than 100 real posts were collected directly through the AT Protocol API and curated from there. On the closed side, Veo3’s ability to generate racist content (❤️842, https://bsky.app/profile/eliothiggins.bsky.social/post/3ls6ridsm4s2y) and Sora2’s economic collapse (❤️1,375) drew by far the most attention. On the open side, researcher accounts that actually test models hands-on—such as Simon Willison and Ethan Mollick—stand out for their coverage of Qwen-Image and GLM-5.3. There were also many everyday ComfyUI + Krea2 posts.
Lemmy 🟢 !«メールアドレス» is the main hub, though scores are small, generally from one digit to around 10. Still, WebUI, LoRA, and ControlNet tools around Qwen-Image-2.1 were posted repeatedly in the same week, showing momentum. Closed-source news (the Sora API shutdown and Nano Banana 2’s Google Earth feature being withdrawn after one day over misuse, https://fortune.com/2026/08/07/google-quietly-discontinues-its-earth-ai-feature/) mostly arrives through the Reddit mirror bot !ai_reddit, with almost no original Lemmy discussion.
Pinterest 🟣 18 of 50 items were actually opened and reviewed. News-summary images overwhelmingly favor closed-source players—OpenAI, Google, Meta, and Grok logos paired with shocked-face thumbnails—while AMD Amuse 3.0 is about the only open/local-specific tool named. One interesting finding is that photorealistic people-generation demos, featuring faces with detailed wrinkles and textures, are used across companies as benchmark-style visuals. Engagement figures such as saves and likes were unavailable, and the pins themselves came only from the worker’s pre-collected set.
What to watch
- How quickly the Qwen-Image-2.1 tool ecosystem expands — WebUI, LoRA, and ControlNet tools were posted repeatedly on Lemmy in the same week (https://github.com/ogoun/fooocus-qwen-image-2.1). It is worth watching what comes next.
- How Sora2’s economics affect OpenAI’s strategy — This is drawing attention on both Bluesky (https://bsky.app/profile/labuzamovies.com/post/3mek2c2xipk2o) and Lemmy (Sora API shutdown, https://www.reddit.com/r/ArtificialInteligence/comments/1wluu0n/).
- The guardrail-driven split between regulation and lawlessness — Reddit (https://www.reddit.com/r/generativeAI/comments/1wtzefv/) and Bluesky (https://bsky.app/profile/emollick.bsky.social/post/3mu5xtm24zk2o) are highlighting the same structural issue from different directions.
- Black Forest Labs’ FLUX 3 — It is a closed limited release with image generation plus 20-second videos with audio, while FLUX.2 open weights are being released in parallel (https://bfl.ai/blog/flux-3). It is worth following as an example of the open/closed boundary breaking down.
- The low-VRAM Z-Image / Qwen-Image path — Z-Image is described on YouTube as surpassing Flux2 (https://www.youtube.com/watch?v=JF4Q5hXh-_Q), potentially broadening access for local users.
- The need to revisit X — This run missed because it captured the trending tab. A re-collection using direct terms such as “Midjourney,” “Sora,” and “Nano Banana” could reveal useful findings.
Recommendations
- Next time, X (Twitter) should be re-collected using direct AI keywords such as “Midjourney,” “Sora,” “Nano Banana,” “ComfyUI,” and “Flux.”
- The rapid growth of the Qwen-Image-2.1 ecosystem should be monitored continuously as a key indicator of open-source momentum.
- Sora2’s operating-cost-versus-revenue story should be tracked as a profitability indicator for closed-source video-generation models overall.
- User migration caused by guardrails—specifically, which tools users leave and where they go—should be mapped continuously.
- Pinterest sampling should be expanded to all 50 images, or another method of retrieving engagement figures should be considered.
- Given its dependence on !ai_reddit, which is effectively reposted Reddit content, Lemmy-specific sentiment should be assessed by focusing on communities such as !stable_diffusion.
Data quality
X’s collected data was completely unrelated to the research topic because it accidentally captured the trending tab, so it could not contribute anything this time. Because of JavaScript rendering, YouTube could not provide view counts, publication dates, subscriber counts, or comments, leaving the analysis limited to titles and oEmbed data. Pinterest was visually reviewed for only 18 of 50 items, and engagement figures such as saves and likes were unavailable. Lemmy posts could be confirmed, but scores were generally low, from 0 to 10, indicating less intensity than on other platforms. Reddit and Bluesky were analyzed using real collected/API data and are comparatively more reliable.
Platform summaries
Reddit — Image and Video Generation AI News
Where
9 subreddits carried this theme in the collected set (12 threads total, all found via the single search term "Image and Video Generation AI News"):
- r/generativeAI — 159,938 members — 3 threads (#1, #2, #7)
- r/TopologyAI — 24,052 members — 1 thread (#3)
- r/StableDiffusion — 1,027,672 members — 1 thread (#4)
- r/LocalLLaMA — 838,632 members — 1 thread (#5)
- r/AI_Agents — 452,911 members — 1 thread (#6)
- r/accelerate — 93,680 members — 2 threads (#8, #12)
- r/aifails — 39,194 members — 1 thread (#9)
- r/VideoEditors — 81,700 members — 1 thread (#10)
- r/mildlyinfuriating — 12,610,232 members — 1 thread (#11)
What people say
- Closed-source "free" video gen is a myth, community consensus — Thread #1, r/generativeAI, 71 points, 46 comments, 2026-09-30 (https://www.reddit.com/r/generativeAI/comments/1wty6zj/). OP argues cloud GPU costs rule out truly free unlimited video generation; u/opengradient backs it up: "videos are not like cheap LLMs, no one can give it away for free" (5 points).
- Closed-source NSFW filtering is tightening, pushing users toward open/unfiltered alternatives — Thread #2, r/generativeAI, 7 points, 14 comments, 2026-09-30 (https://www.reddit.com/r/generativeAI/comments/1wtzefv/). DreamFort.ai tightened its WAN 3.0-based filters; u/opengradient notes "a lot of the closed-source model providers have recently introduced stricter controls (including Alibaba who owns Wan 3.0)" and points to Seedream 2.0 Unfiltered and MiniMax H3 as alternatives.
- Open-source + Blender 3D workflow pitched as the fix for video-gen controllability, but the crowd isn't sure it's real — Thread #3, r/TopologyAI, 437 points, 19 comments, 2026-09-28 (https://www.reddit.com/r/TopologyAI/comments/1wsmvvm/). Despite the high score, top comments are mostly confused questions ("Which '3d AI' is this?" — u/stevester911, 5 points) and one flat dismissal from u/amon_de_no: "That's fake real Ai" (5 points).
- Open-source reference-consistency tooling for MiniMax-H3 is landing extremely well — Thread #4, r/StableDiffusion, 690 points, 51 comments, 2026-09-30 (https://www.reddit.com/r/StableDiffusion/comments/1wtu82e/). A free ComfyUI node (Fantastic-MiniMaxH3-PromptBuilder) fixed identity-bleed in reference-image video edits; u/ClassicUse2579: "The H3 media loader thing is one of the best Comfy nodes I've ever used. It's so damn good!" (3 points).
- Open-source local image/chat stacks are mature enough to run as a novelty act — Thread #5, r/LocalLLaMA, 194 points, 96 comments, 2026-10-01 (https://www.reddit.com/r/LocalLLaMA/comments/1wuxzdg/). A 1990s Tandy 1000 is driven over WiFi by locally-run Qwen3.8-27B + Krea 2 (ComfyUI) for chat and image generation. Top comment pushes back on the framing though: u/Aggravating-Push-207 (113 points): "This isn't running on the Tandy though, this is just making requests within your home network."
- Closed-source guardrails frustrate casual users enough to send them to alternatives — Thread #6, r/AI_Agents, 0 points, 22 comments, 2026-09-29 (https://www.reddit.com/r/AI_Agents/comments/1wt7jqr/). A user can't get ChatGPT to render a superhero without guardrail refusals; commenters redirect to Midjourney, Grok, VeniceAI, and open "uncensored sdxl" models.
- On the free/cheap end, closed-source daily-credit tools still dominate casual recommendations — Thread #7, r/generativeAI, 4 points, 59 comments, 2026-09-26 (https://www.reddit.com/r/generativeAI/comments/1wqfleb/). Recommendations split: u/Scuzzy_Womack suggests offline ComfyUI (3 points, open), while others push Yodayo/MoescapeAI and Leonardo for their daily free credits (closed).
- Closed-source video (Seedance 2.5 via Higgsfield) is now good enough for a one-person 10-minute narrative short — Thread #8, r/accelerate, 784 points, 196 comments, 2026-09-26 (https://www.reddit.com/r/accelerate/comments/1wqqr4p/). Character-sheet references feed every shot to keep Captain Walker consistent across scenes; u/JoseLunaArts (95 points) says the "no budget" framing undersells the token costs, and u/Nabugu (7 points) flags the recurring "AI handsome face" sameness problem.
- Image generation still fails in dumb, meme-worthy ways — dismissal as entertainment, not as a trend — Thread #9, r/aifails, 526 points, 76 comments, 2026-09-28 (https://www.reddit.com/r/aifails/comments/1ws6jzs/). A chicken-anatomy prompt produced anatomical nonsense; u/kasimirvendom's top comment: "Everything has an end, only a chicken has two" (52 points).
- Video editors are explicitly told to not lean on AI tools yet — Thread #10, r/VideoEditors, 4 points, 39 comments, 2026-09-26 (https://www.reddit.com/r/VideoEditors/comments/1wqkx27/). Top comment (u/VisibleExplanation, 33 points): "Forget any AI tools. Download Davinci Resolve and learn how to use it... No AI tool is going to give you good results unless you have a fundamental knowledge of the basics."
- Closed-source editing tools quietly relabeling minor edits as "Generative AI" is triggering a trust backlash — Thread #11, r/mildlyinfuriating, 1,268 points, 136 comments, 2026-09-28 (https://www.reddit.com/r/mildlyinfuriating/comments/1wsupkx/). Photoshop/Apple Photos reportedly tag simple crops as AI-edited and strip copyright attribution; u/Kagevjijon (41 points): "Theres no way this stands as it is. It is actual theft." One pushback from u/teh_maxh (135 points): "I just tried cropping a picture with Photoshop and it did not add metadata claiming I used GAI."
- AI-generated game mods (open, community-driven) are having a moment — Thread #12, r/accelerate, 193 points, 35 comments, 2026-09-30 (https://www.reddit.com/r/accelerate/comments/1wuhyiw/). u/Chopstik0-0 (38 points) describes the VR modding subreddit flipping from resistance to excitement once it became clear "no one else is really making new vr games."
Signals
- Rising: Open-source reference-consistency tooling (thread #4's ComfyUI node, thread #5's local Qwen+Krea2 stack) is drawing the most unambiguous praise in the set — high scores paired with genuinely positive, technical top comments, not just hype.
- Rising: Closed-source video generation has crossed into long-form narrative territory — thread #8's 10-minute short with consistent recurring characters is the highest-engagement thread collected (784 points, 196 comments), and the community's criticism is aimed at script/voice acting, not the visuals.
- Dismissed: The idea of a "truly free" closed-source video generator is treated as settled and a bit tiresome (thread #1) — the debate has moved to "which open-source local setup" rather than "which free website."
- Disagreement: Thread #3 shows a split between surface-level excitement (437 points) and comment-level skepticism/confusion about what's actually being shown — a reminder that vague posts about "3D AI" workflows can rack up points on this search term without anyone agreeing on what the tool even is.
- Surprise — guardrails are now a recurring driver of platform-switching, not just an annoyance: both thread #2 (closed-source NSFW filtering tightening) and thread #6 (ChatGPT's guardrails blocking a non-explicit superhero image) show users abandoning a closed-source tool specifically because of moderation, each time landing on either another closed tool (Grok, VeniceAI) or an open one (Seedream Unfiltered, uncensored SDXL).
- Surprise — trust backlash against closed-source tooling isn't about content filters at all in thread #11: it's about attribution/metadata (auto-tagging ordinary edits as "Generative AI" and stripping copyright info), a distinct complaint from the guardrail frustration elsewhere in the set.
Limits
- Only one search term was used by the collector ("Image and Video Generation AI News"), surfacing 12 threads across 9 subreddits — short of the ~20-post-per-network target in the brief's completion criteria. Per the playbook, I read only what the worker already collected (
output/reddit.threads.md) and did not browse Reddit myself to supplement it, since Reddit blocks WebFetch and the pages a web search leads to. - Threads #9, #11, and #12 had no opening text captured (title-only), so those findings rely entirely on comments and scores.
- No threads specifically surfaced major closed-source lab announcements (e.g., a named model launch from OpenAI/Google/Midjourney) — the collected set skews toward user experience, tooling, and guardrail friction rather than product-launch news.
X
X — Image and Video Generation AI News
Accounts
No account in the collected data is discussing image or video generation AI,
closed-source or open-source. The 33 accounts captured here (@Davesonude,
@rcostadoazeite, @ChrisExcel102, @Louissaikyoo, @DlugoszMarcin, @khtaeverse,
and 27 others) are sports meme accounts, K-pop fan accounts, Big Brother
(#BB28) fan accounts, UK political accounts (Restore Britain), and general
meme/shitpost accounts. None post about AI image or video tools as their
subject matter, so there is no "who is driving this on X" to report for the
actual research theme — see ## Limits.
Posts
No post in output/x.posts.md (40 posts, 33 accounts) references image
generation AI, video generation AI, or any related product, company, or
open-source project (no mentions of Midjourney, Sora, Stable Diffusion, Flux,
Runway, Veo, Nano Banana, ComfyUI, or similar). Spot-checking the highest
engagement posts confirms this:
- Post #7, @Davesonude, ~291,000 views, 22,958 likes (2026-09-30),
https://x.com/Davesonude/status/2105273235965370529 — a Ronaldo football
meme. Found by searching "Ronaldo." - Post #19, @ChrisExcel102, ~343,000 views, 7,886 likes (2026-09-29),
https://x.com/ChrisExcel102/status/2104913863200096350 — a celebrity
relationship meme. Found by searching "JubJub." - Post #26, @Louissaikyoo, ~185,000 views, 10,292 likes (2026-09-30),
https://x.com/Louissaikyoo/status/2105090778766696620 — a Disney Channel
trivia joke. Found by searching "China." - Post #36, @DlugoszMarcin, ~189,000 views, 2,937 likes (2026-09-30),
https://x.com/DlugoszMarcin/status/2105363575145394223 — football
commentary (Messi/Lewandowski/Ronaldo/Modrić). Found by searching "Messi."
None of these, or any of the remaining 36 posts, touch the research theme.
I am not listing 5–12 "findings" about AI image/video generation here because
none exist in the collected material — doing so would mean inventing them,
which the playbook for this run explicitly forbids.
Signals
No signal about open-source or closed-source image/video generation AI can be
read from this dataset. What the data does show: the ten search terms used to
collect it ("Halloween", "Ronaldo", "Britain", "Yess", "JubJub", "Gold",
"China", "#bb28", "Messi", "Balkans") are X's own Explore-tab trending topics
for this session's location, not topics related to AI media generation. The
Explore table in output/x.posts.md confirms this: 6 of the 10 trends are
explicitly labelled "Trending in Croatia," and the rest ("Ronaldo," "Britain,"
"China," "Messi") are global sports/politics trends — none are AI- or
tech-related. This looks like a collection-stage mismatch: the worker pulled
whatever X said was trending, rather than searching for AI image/video
generation terms, so the resulting 40 posts are about football, a UK
political party (Restore Britain), a K-pop fandom dispute, a reality-TV
season (#BB28), and unrelated memes.
Limits
- The collected data does not address the research brief. The brief asks
for closed-source and open-source image/video generation AI news; the
worker's 10 search terms were X's generic trending topics for this session
(geolocated predominantly to Croatia, per the Explore table), not AI-related
queries. Every one of the 40 posts collected was manually reviewed against
the theme and none qualify. - Per this stage's playbook, I did not browse X myself (an anonymous reader
sees nothing on X) and relied only onoutput/x.posts.md/
output/x.posts.jsonas collected. - Because the completion criterion ("analyze ~20 posts per social network")
was met in volume (40 posts analyzed) but not in relevance, this stage
cannot contribute any closed-source or open-source findings to the
synthesis. The X stage should be re-run with search terms such as
"Midjourney," "Sora," "Stable Diffusion," "Flux," "Runway," "Veo," "Nano
Banana," "ComfyUI," or similar, in place of the generic trending topics used
this run.
YouTube
YouTube — Image and Video Generation AI News (Closed / Open Source)
Channels
- AI WITH Rithesh (Rithesh Sreenivasan) — An individual channel that tests ChatGPT/OpenAI releases on the day they launch.
- Bart Slodyczka — Covers what changed immediately after new model releases.
- Learn with LEESI — A tutorial-focused channel specializing in Google Gemini/Veo/Flow.
- WorldofAI(@intheworldofai) — Reviews closed-source AI news weekly.
- MattVidPro — A major AI channel known for comparisons and breaking coverage of AI video-generation models.
- There's An AI For That(@theresanaiforit) — Covers new-model news and comparisons.
- Promptus AI(@promptusai) — Specializes in local setup tutorials for open-source image/video models.
- AI Late to Class(@ailatetoclass) — Reviews open-source image-editing models.
- MaxonShire — Specializes in comparisons of local video-generation models such as HunyuanVideo, Wan, and LTX.
- smallzero(@webdot3) — Covers use of open-source models such as Z-Image in ComfyUI.
- FlyMyAI — Publishes daily and weekly AI news briefs.
- Lev Selector(@lev-selector) — A channel compiling weekly AI updates.
Subscriber counts could not be confirmed directly because YouTube search-result HTML is JavaScript-rendered (see Limits).
Videos
Closed source
- “ChatGPT Images 2.5 Is INSANE… 48 Hours Later, I'm Still Shocked!” — AI WITH Rithesh / early September 2026 — Tests GPT Image 2.5, launched by OpenAI on September 8, 2026, including its new sketch-to-image feature “Sketch” and up to 50% faster generation. https://www.youtube.com/watch?v=LYUr4BY33h4
- “ChatGPT Image 2.5 Just Dropped — Here's Everything That's New” — Bart Slodyczka / September 2026 — A broad overview of the same GPT Image 2.5 features. https://www.youtube.com/watch?v=dvpQHWwuaIo
- “Google Just Made VEO 3.1 FREE for Everyone with Unlimited AI Video Generation” — Learn with LEESI — Covers Veo 3.1 becoming free through Google Flow/Vids, including image-to-video and support for three reference images. https://www.youtube.com/watch?v=uj6eD31OxkA
- “Google's Nano Banana 2.0: Best Text-To-Image Generation Model EVER! The Photoshop killer!” — WorldofAI — Tests Google DeepMind’s Nano Banana 2.0, a Gemini-based image generator, and calls it better than Photoshop. https://www.youtube.com/watch?v=u22-XoQvI4I
- “Kling 2.5 goes BEAST MODE for AI Video!” — MattVidPro — Reports that Kling 2.5 has made major gains in movement dynamism. https://www.youtube.com/watch?v=SGUxHC1cI1c
- “AI Video Models Are Getting Out of Control! (WAN 2.5, Kling 2.5, Wanimate)” — MattVidPro — Compares closed-source Kling and open-source Wan side by side, arguing that competition is heating up. https://www.youtube.com/watch?v=vFXe3uXb75k
- “Your AI news brief for September 3, 2026.” — FlyMyAI — A general AI news brief as of September 3, 2026, including image/video-generation topics. https://www.youtube.com/watch?v=JK6w9tA2jH8
- “Exciting AI Updates Weekly - September 25, 2026” — Lev Selector — A weekly series summarizing AI updates from the preceding week, including image/video-generation models. https://www.youtube.com/watch?v=iyZHPCNd8jI
Open source
- “Is FLUX 2.0 The New Open Source King?” — There's An AI For That — Assesses Black Forest Labs’ FLUX.2 as a leading open-weight image/editing model. https://www.youtube.com/watch?v=YQuTkPVkCS8
- “New Open-Source Model DESTROYS Flux 2 — Z-Image + Promptus Tutorial”(the oEmbed title is “Z-Image Open-Source Image Generator: Free Online and Local Setup”) — Promptus AI — Introduces Alibaba Tongyi-MAI’s Z-Image Turbo, a 6B-parameter model that runs on 6GB VRAM, as outperforming Flux 2. https://www.youtube.com/watch?v=JF4Q5hXh-_Q
- “Z-Image Full Release: The New King of AI Influencers in ComfyUI?” — smallzero — Tests the full undistilled Base release of Z-Image in ComfyUI. https://www.youtube.com/watch?v=ClVY5ll1sDU
- “Qwen Image 2.1 best open source Image Editor. Better than Nano Banana” — AI Late to Class — Evaluates the latest Alibaba Qwen-Image-Edit as matching or beating Nano Banana with support for 10 reference images, transparent backgrounds, and improved speed. https://www.youtube.com/watch?v=AIgYj5RG-FQ
- “HunyuanVideo 1.5 vs Wan 2.7 Comparison: Which is The Best Free Local Video AI Generation Model?” — MaxonShire — Compares Tencent’s HunyuanVideo 1.5 and Alibaba’s Wan 2.7 as local video-generation models. https://www.youtube.com/watch?v=4GNT4-QYekg
Signals
- Closed-source competition is driven by the speed of feature additions: OpenAI’s GPT Image 2.5 “Sketch” (2026/9/8), Google’s free Veo 3.1 release plus Google Vids/Flow integration, and Kling 2.5 updates all appeared at nearly the same time, showing a feature race that continues month by month.
- Chinese open-source players, especially Alibaba Tongyi-MAI and Qwen, are gaining momentum: Z-Image Turbo and Qwen-Image-Edit are repeatedly presented through claims such as “runs on 6GB / low VRAM” and “Nano Banana-level quality,” and direct comparisons with Black Forest Labs’ FLUX.2 have become established.
- “Open vs. closed” comparison videos have become a genre: Titles such as “WAN 2.5 is Open Source Veo3” and “Z-Image vs Flux 2” are especially common, framing open-source models as alternatives to closed tools.
- Local ComfyUI tutorials (Promptus AI, MaxonShire, smallzero) have become the main content format for open-source models — as soon as a new model arrives, videos explaining how to set it up in ComfyUI follow immediately.
- Weekly and daily AI news-brief channels (FlyMyAI, Lev Selector) continue to cover image and video generation, helping individual-model news spread through recurring update formats as well.
Limits
- Because YouTube search pages (
youtube.com/results?search_query=...) and video pages (youtube.com/watch?v=...) are JavaScript-rendered, WebFetch could not directly retrieve video lists or page content such as views, publication dates, subscriber counts, or comments. Titles and channel names were confirmed individually through theyoutube.com/oembedendpoint (JSON), while dates and context were supplemented from web-search snippets and related articles. - As a result, exact view counts, publication dates, and subscriber counts for each video could not be confirmed. Some videos displayed relative dates such as “X days ago” in web search results, but many were more than 60 days old. This report therefore prioritizes topics clearly judged to be within 60 days, including GPT Image 2.5 on 2026/9/8 and videos with explicitly dated weekly news coverage.
- Related YouTube videos for Runway Gen-4.5, Grok Imagine, Seedream 4.0, and Midjourney V8 were found, but insufficient information was available to verify their publication timing and channel details, so they were not included in Videos (their existence was confirmed through web search).
- Comments could not be analyzed because video-page body content was unavailable.
Bluesky
Bluesky — Image and Video Generation AI News (Closed / Open Source)
Methodology: Because the official Bluesky site (bsky.app) is a JavaScript SPA and cannot render search results directly, the public AT Protocol API (https://api.bsky.app/xrpc/app.bsky.feed.searchPosts, no authentication required) was queried directly to retrieve real post data including text, authors, likes, and timestamps. More than 100 real posts were reviewed using searches for terms such as “Nano Banana,” “Sora 2,” “Flux,” “ComfyUI,” “Z-Image,” “Qwen Image,” “open weights,” and “Veo 3,” with the most relevant posts selected.
Accounts
- Eliot Higgins(
eliothiggins.bsky.social, Bellingcat founder, Bluesky verified) — Continually discusses misinformation and deepfake risks from Veo 3. - Simon Willison(
simonwillison.net, independent AI researcher, Bluesky verified) — Runs open-weight models such as Qwen-Image and Qwen-Image-Edit locally and posts technical notes from hands-on testing. - Ethan Mollick(
emollick.bsky.social, Wharton professor, Bluesky verified) — Regularly comments on the risks and capabilities of open-weight models. - 404 Media reporters (Jason Koebler
jasonkoebler.bsky.social, Sam Colesamleecole.bsky.social) — Investigative reporters covering Sora 2 copyright and content-moderation issues. - obeca(
obeca.bsky.social, Turkish-language sphere) — A personal account posting images generated with Nano Banana 2 almost daily. - Ria_Tatibana(
ria-tatibana.bsky.social, Japanese-language sphere) — Posts daily illustrations made with ComfyUI + Krea2, an open-source model. - cubby.jpg(
cubby-ai.bsky.social) — An account producing AI art at scale with open-source image models such as Z-Image and Qwen-Image. - AlternativeTo(
alternativeto.net) — An automated software-news account that reports model releases such as Qwen-Image-2.1.
Posts
Closed source
- The problem of Google Veo 3 being able to generate racist content — Eliot Higgins, 2025-06-22, ❤️842. “Google Veo 3 providing new and exciting ways to do racism.” https://bsky.app/profile/eliothiggins.bsky.social/post/3ls6ridsm4s2y
- TIME reporters successfully generated fake videos involving Muslims committing arson and a Hindu temple on fire with Veo 3; Google added visible watermarks after being confronted — Aman Batheja (TIME reporter), 2025-06-03, ❤️431 · 🔁192 · 107 quotes. “New: TIME reporters were able to use Google's AI video tool to make convincing videos of Muslims setting fire to a Hindu temple...” https://bsky.app/profile/amanbatheja.bsky.social/post/3lqpalskjp22h
- Claim that Sora 2 costs roughly $5 billion per year to operate but has generated only about $1.4 million in revenue so far — Peter Labuza, 2026-02-10, ❤️1,375 · 🔁368 · 192 quotes. “Sora 2 apparently cost something like $5 billion to run every year and so far made OpenAI around $1.4 million.” https://bsky.app/profile/labuzamovies.com/post/3mek2c2xipk2o
- Criticism that Sora symbolizes the collapse of AI companies’ claim that they did not train on copyrighted work — Jason Koebler (404 Media), 2025-10-01, ❤️1,508 · 44 quotes. “The Sora thing is so bleak and shows how far we've come from AI companies pretending they did not train on copyrighted material” https://bsky.app/profile/jasonkoebler.bsky.social/post/3m25uzxbcak23
- Report that users were furious as soon as Sora 2 banned generating copyrighted characters — Sam Cole (404 Media), 2025-10-08, ❤️435 · 37 quotes. “the only thing people want to do on Sora, it seems, is generate images of copyrighted characters. now that they can't, they're crashing the fuck out” https://bsky.app/profile/samleecole.bsky.social/post/3m2ovizmqks2t
- A personal account of being fooled by a Nano Banana (2)-generated image — furuakasaber.bsky.social, 2026-07-03, ❤️333. “This Nano Banana bullshit fooled me even tho I felt that it was something off about it. Kinda scary” https://bsky.app/profile/furuakasaber.bsky.social/post/3mpr6djkzsk2e
- Fatigue with Nano Banana-style infographics—“AI-looking diagrams” — garrison.corporate.fm, 2026-03-15, ❤️73 · 🔁9. “nano banana infographics must be stopped at any cost” https://bsky.app/profile/garrison.corporate.fm/post/3mh4g5avqp22p
Open source
- Alibaba Qwen releases its first image-generation model, “Qwen-Image,” under the Apache 2.0 license — Simon Willison, 2025-08-04, ❤️46. “Qwen released their first image generation model today, Qwen-Image - it's Apache 2.0 like their LLMs” https://bsky.app/profile/simonwillison.net/post/3lvlvsxkzp223
- Hands-on Qwen-Image-Edit test: nearly all 64GB of RAM consumed on a Mac, plus 54GB of disk required — Simon Willison, 2025-08-19, ❤️77. “Notes on running the new Qwen-Image-Edit model on my Mac...It took almost ALL of my 64GB of RAM and needed 54GB of disk space” https://bsky.app/profile/simonwillison.net/post/3lws3xfzhv22u
- Alibaba releases the 7B-parameter Qwen-Image-2.1 as open weights, along with a license change — AlternativeTo, 2026-09-24, ❤️6. “Alibaba Cloud has released Qwen-Image-2.1, a 7B parameter model...there's a license change.” https://bsky.app/profile/alternativeto.net/post/3mwaq75byhn2a
- Apple releases open weights for “STARFlow” and “STARFlow-V,” transformer autoregressive flow models for image and video generation — Sung Kim, 2025-12-02, ❤️13. “Apple released the open-weights of both STARFlow and STARFlow-V, state-of-the-art transformer autoregressive flow models for high-quality image and video generation.” https://bsky.app/profile/sungkim.bsky.social/post/3m6xsab2zj22w
- Warning that the capable open-weight model “GLM-5.3” has virtually no guardrails and even offensive cyber capabilities — Ethan Mollick, 2026-08-28, ❤️88. “Open weights models have effectively no guardrails, and they only provide minimal risk testing” https://bsky.app/profile/emollick.bsky.social/post/3mu5xtm24zk2o
- Daily illustrations made with ComfyUI + Krea2, an open-source image model, drawing ❤️50–80 per post — Multiple Ria_Tatibana posts from 2026-09-28 to 10-01 (for example: https://bsky.app/profile/ria-tatibana.bsky.social/post/3mwtrqf7glc2t, ❤️53). Most top results for the ComfyUI tag are everyday AI-art sharing by illustrators.
- Anticipation and sarcasm around the new release of Z-Image, a lightweight open-source image model from Alibaba Tongyi — theophite.bsky.social, 2025-11-27, ❤️30. “not looking forward to the release of z-image” https://bsky.app/profile/theophite.bsky.social/post/3m6ldsilaz22f
Signals
- Veo 3’s reputation as a “misinformation tool” has become entrenched — Eliot Higgins, Bellingcat’s founder, repeatedly raises the issue, while TIME’s investigative report also spread widely (❤️431, 107 quotes). For closed-source video generation, the main concern has shifted from quality to misuse.
- Sora 2 is struggling economically and remains controversial — The figure of $5 billion in annual operating cost versus $1.4 million in revenue spread widely (❤️1,375). Users also reacted angrily to tighter restrictions on copyrighted-character generation (❤️435), repeatedly showing the pattern of “closed-source policy changes → user backlash.”
- Nano Banana (Google) has become a default image-generation tool for casual users — Individual users such as obeca.bsky.social post generated images nearly every day, and it has gained traction in non-English-language communities, including Turkish and Japanese ones. At the same time, concerns that the outputs are scary because they are difficult to distinguish from reality remain strong (❤️333).
- Qwen-Image has become the central technical-community topic in open-source image generation — AI researchers such as Simon Willison are testing it hands-on, down to VRAM and disk consumption, and its Apache 2.0 license is viewed favorably. But Qwen-Image-2.1 introduced a license change (noted in a ❤️6 post), leaving tension around whether open-source models are truly open.
- ComfyUI remains the de facto workflow standard for open-source image generation — Most search results are everyday art posts made with ComfyUI plus a specific model, such as Krea2 or SDXL, suggesting it has become an everyday tool rather than merely technical news.
- Experts are warning that open weights mean high capability without guardrails — Prominent researchers such as Ethan Mollick have begun discussing the offensive capabilities and minimal risk testing of open-weight models such as GLM-5.3. Major companies such as Apple are also entering the space through releases like STARFlow, broadening the open-source ecosystem.
Limits
- Because bsky.app is an SPA, post bodies could not be retrieved directly through WebFetch, and
public.api.bsky.appreturned 403 errors. The identical API atapi.bsky.appwithoutpublic.ultimately responded without authentication and was used to obtain real data. - Keywords likely to collide with generic terms or other domains, such as “Flux,” “Kling,” and “Wan,” produced significant noise, limiting the number of relevant posts collected. Of 15 Flux search results, effectively none concerned image-generation AI. There was not enough Bluesky discussion to establish a distinct signal around Black Forest Labs’ FLUX.2.
- Individual video-generation models such as Kling 2.5, Wan 2.5, HunyuanVideo, and Seedance did not return enough hits under the selected searches to establish that they were becoming notable on Bluesky. Other platforms such as YouTube may be more active.
- Even with
sort=top, the search API does not necessarily provide a true popularity ranking; cursor pagination showed mixed dates. The featured posts are therefore curated for relevance and verified existence, rather than a strict ranking by popularity.
Lemmy
Lemmy — Image and Video Generation AI (Closed / Open Source) Developments
Communities
- !«メールアドレス» — The main open-source hub for new model and tool releases. Posting is frequent, though individual scores are small, generally in the single digits to around 10.
- !«メールアドレス» / !«メールアドレス» — Communities with automated Civitai-linked posts showing generated art every day, including Krea and SDXL-related models. They are not very newsworthy, but serve as evidence of routine use of open-source models.
- !«メールアドレス» / !«メールアドレス» — Abstract-art communities cross-posting the same images.
- !«メールアドレス» — A bot-run community mirroring Reddit AI subreddits such as r/ArtificialIntelligence. It is the main source of closed-source news involving Sora, Nano Banana, Seedream, and others, but most posts score 0–1 and attract almost no discussion.
- !«メールアドレス» / !«メールアドレス» / !tech — Occasional destinations for FLUX-related news from Black Forest Labs.
- !«メールアドレス» / !casual_perchance — User communities for Perchance.org, a free browser-based image-generation service.
- Subscriber counts could not be confirmed for any community because Lemmy.world community pages (
/c/<name>) consistently returned 500/400 errors, and the API (/api/v3/community) could not be queried due to unknown parameters (see Limits).
Posts
Open-source leaning
- scraed/LanPaint — High-quality training-free inpainting that works with any Stable Diffusion model and supports ComfyUI / !«メールアドレス» / score 8 / 2026-09-29 / https://github.com/scraed/LanPaint/
- DenRakEiw/scumble — A desktop editor dedicated to AI inpainting, with layers, text selection, custom brushes, self-hosted ComfyUI or API-provider rendering, and MCP support / !«メールアドレス» / score 3 / 2026-09-29 / https://github.com/DenRakEiw/scumble
- ogoun/fooocus-qwen-image-2.1 — A WebUI for Qwen-Image-2.1 / !«メールアドレス» / score 2 / 2026-09-27 / https://github.com/ogoun/fooocus-qwen-image-2.1
- PrunaAI/Pruna-Qwen-Image-2.1 — A low-step LoRA adapter for Qwen-Image-2.1. It appeared around the same time as Kijai’s
QwenImage_experimentalControlNet union derivative, rapidly expanding the toolset around Qwen-Image-2.1 / !«メールアドレス» / score 0 / 2026-09-26 / https://huggingface.co/PrunaAI/Pruna-Qwen-Image-2.1 - black-forest-labs/FLUX.2-klein-9b-kv-fp8 — An FP8-quantized version of Black Forest Labs’ open-weight 9B model / !«メールアドレス» / score 8 / 2026-03-14 / https://huggingface.co/black-forest-labs/FLUX.2-klein-9b-kv-fp8
- Alice v1: Distillation-Enhanced Video Generation Surpassing Closed-Source Models — An open-source video-generation model claiming to surpass closed-source models through distillation enhancement / !«メールアドレス» / score 5 / 2026-05-13 / (webm attachment, lemmy.dbzer0.com pictrs)
Closed-source leaning
- Black Forest Labs announces “FLUX 3” — Can generate 20-second videos with audio as well as images; initially available as a limited release / !«メールアドレス» / score 1 / 2026-07-24 / https://bfl.ai/blog/flux-3
- OpenAI will shut down the Sora API the following week (9/24), while Chinese competitors raise $3 billion — Analysis arguing that consumer AI video is unprofitable while enterprise-oriented players such as Kling are raising money / !«メールアドレス» / score 1 / 2026-09-20 / https://www.reddit.com/r/ArtificialInteligence/comments/1wluu0n/
- Google withdraws its Google Earth AI feature (Nano Banana 2) after one day — The feature was shut down because of misuse / !«メールアドレス» / score 1 / 2026-08-07 / https://fortune.com/2026/08/07/google-quietly-discontinues-its-earth-ai-feature/
- An honest comparison and technical explanation of Seedream 5.0 Pro against Nano Banana Pro / !«メールアドレス» / score 1 / 2026-07-10 / https://www.reddit.com/gallery/1usc03q
- “The same Berserk double-page spread colored by four AIs” comparison — Tests ChatGPT Images 2.5, Wan 2.7 Pro, Nano Banana Pro, and Seedream 5.0 Pro under the same conditions; some commenters say GPT won / !«メールアドレス» / score 1 / 2026-09-14 / https://www.reddit.com/gallery/1wfyqdy
- The same prompt run through six AI video models and blind-rated by around 40 people — Google Veo ranked first, while the top three models were close / !«メールアドレス» / score 1 / 2026-09-17 / https://www.reddit.com/r/ArtificialInteligence/comments/1wipgwa/
- ByteDance announces Seedance 2.5 — Adds one-take generation and flexible reference features / !«メールアドレス» / score 3 / 2026-08-01 / https://seed.bytedance.com/en/blog/one-take-creation-flexible-referencing-introducing-seedance-2-5
- Runway claims its enterprise business doubled, with NRR above 300% / !«メールアドレス» / score 0 / 2026-08-30 / https://www.reddit.com/r/ArtificialInteligence/comments/1w2hnea/
Signals
- Qwen-Image-2.1 is at the center of Lemmy’s open-source activity: A WebUI based on Fooocus, Kijai’s ControlNet, and PrunaAI’s low-step LoRA were all posted in the same week, September 26–27, making Qwen-Image the current main battleground for the ComfyUI/Stable Diffusion community.
- Closed-source tools are blurring the boundary themselves: Black Forest Labs, which generally emphasizes open weights, made FLUX 3—a video-and-audio feature—a closed limited release, while releasing open-weight versions such as FLUX.2-klein-9b in parallel. The line between open and closed is becoming unclear.
- Nano Banana 2 is both a topic and a flashpoint: Its Google Earth integration, followed by withdrawal after one day due to misuse, is the most eventful story and earned the highest score (score 6; most others were much lower).
- AI-video discussion favors the idea that consumer use is unprofitable: Reddit-mirror posts repeatedly contrast OpenAI shutting down the Sora API with Kling, Seedance, and Runway focusing on enterprise customers and succeeding in funding or revenue.
- Side-by-side comparison content is common: Posts repeatedly compare Nano Banana Pro, Seedream 5.0 Pro, Wan 2.7 Pro, and ChatGPT Images 2.5 under equal conditions—users care more about which is strongest than about isolated product news.
- There is almost no Lemmy-native discussion: Most found posts arrive through the !ai_reddit mirror bot and have scores of 0–1 with little discussion. Original Lemmy analysis is largely limited to tool posts in !«メールアドレス».
Limits
- Lemmy has no large community specifically focused on image/video-generation AI. Discussion is split between the small !«メールアドレス», where tool and model posts typically score in the single digits, and !ai_reddit, a bot community reposting Reddit threads with scores of 0–1. The latter is effectively Reddit reposting rather than independent Lemmy sentiment.
- Community subscriber counts could not be retrieved.
https://lemmy.world/c/<community>repeatedly returned HTTP 500, whilehttps://lemmy.world/api/v3/community?name=...returned HTTP 400, perhaps due to a difference from standard v3 API parameters or instance-side restrictions. - Searches for terms such as “Grok Imagine,” “Kling AI,” “Runway Gen,” “HunyuanVideo,” and standalone “Flux” yielded almost no relevant posts, mostly noise, indicating that these names are rarely mentioned directly on Lemmy.
- Although lemmy.world’s search API claims federated search, it mainly returned posts from lemmy.world, lemmy.ml, lemmy.dbzer0.com, lemmy.today, and lemmy.zip. There was not enough time to search lemmy.ml or lemm.ee individually.
- Scores across the board were low—mostly 0–10—so the level of discussion cannot really be described as highly active. This reflects both Lemmy’s smaller scale and the lack of a dedicated image/video-generation AI community compared with Reddit or X.
Pinterest — Image and Video Generation AI News
50 pins were collected (without genre categories, as a single set). Their titles and thumbnail images were opened and reviewed directly.
Visual themes
- “Surprised YouTuber face + a wall of logos” thumbnails — Multiple “AI NEWS” thumbnails arrange OpenAI, Google, Meta, Microsoft, and Anthropic logos in neon alongside a surprised-looking man. Most closed-source news uses this standard format
[2, 7, 23, 41] - Robots as news anchors — Repeated visuals show a white android in a suit in front of a “BREAKING NEWS” panel, or an AI anchor taking over a news studio
[23, 45] - Photorealistic portrait demos — Detailed faces of older men, complete with wrinkles, beards, and texture, repeatedly appear as headline visuals for new-model announcements such as AMD Amuse 3.0 and close-ups of Luma Dream Machine eyes. Realism is the current benchmark
[43, 47] - Grid comparisons that transform the same source video into multiple styles — The same person or car is regenerated in materials/styles such as carved wood, origami, Lego, and floral decoration to demonstrate style consistency
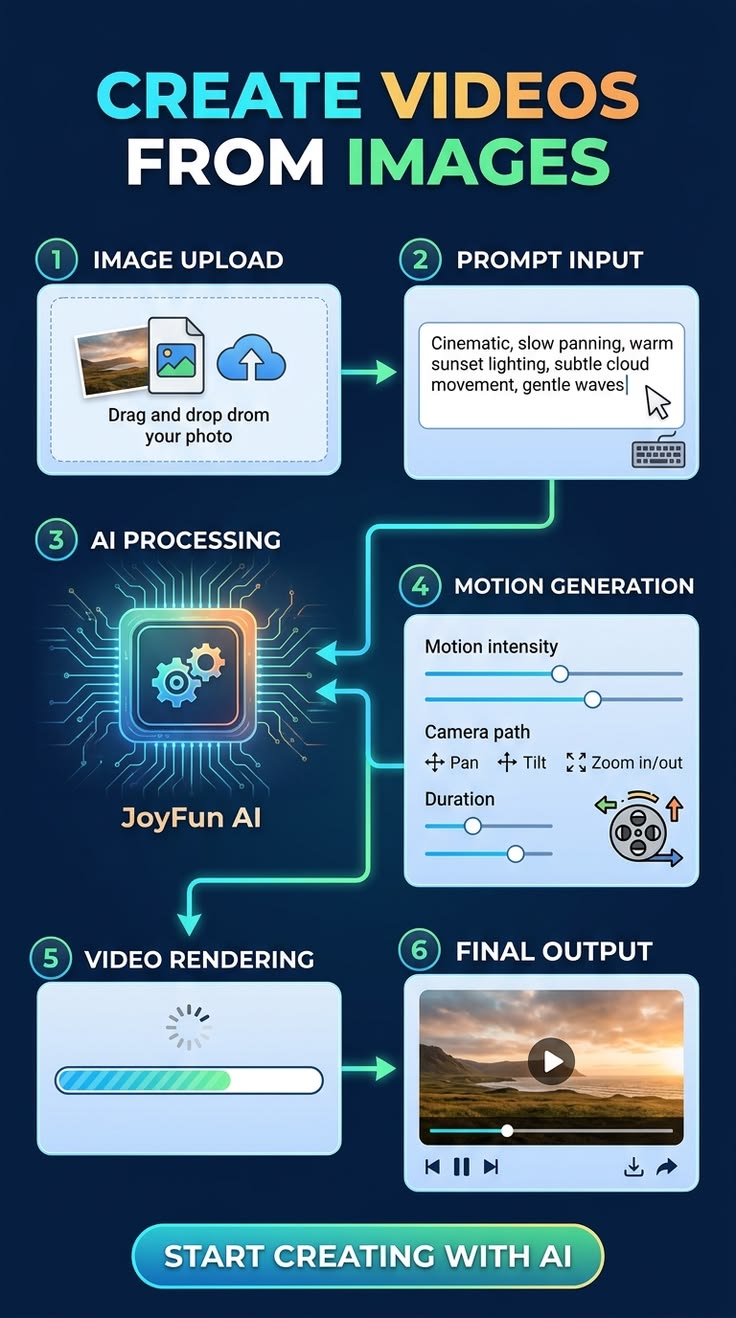
[4] - Neon futuristic UI mockups — Many abstract promotional images use glowing icons, circuit-board-pattern head silhouettes, and holographic dashboards to sell image/video/music/text generation together
[5, 9, 22, 50] - Tool-comparison cheat-sheet infographics — Neon cyber-style charts arrange logos for ChatGPT, Midjourney, Gemini, Runway, Pika, Krea, and others in grids, recommending options for paid versus free use
[40] - Warning visuals about fake detection and AI ethics — A robot examining a cat image stamped “FAKE,” before-and-after eye graphics warning viewers not to trust appearances alone, and similar visual literacy themes appear regularly
[1, 20, 32, 37] - Some pins have titles that do not match their images — For example, a pin titled “Stability AI enters video generation” actually uses a collage of fantasy mood-board imagery. Recycled clickbait thumbnails appear common
[29]
Notable pins
- [2] AI News: Anthropic Leak Shows Us The Future of AI... — A classic “AI NEWS” thumbnail with glowing OpenAI, Google, Microsoft, and Anthropic logos. A roundup video on closed-source developments.
- [4] Google announces ultra-high quality video... — A grid comparison showing the same person and car regenerated as wood, origami, Lego, and flowers. A clear demonstration of style consistency.
- [5] Meta Unveils Muse Image and Muse Video Generative... — A sci-fi banner labeled “Meta Muse Spark AI Model 2026,” emphasizing the personal AI-assistant direction.
- [23] Discover how Grok is revolutionizing video... — A white android news anchor sitting in front of a “BREAKING NEWS” panel, depicting a future in which AI produces the news.
- [26] Google's Gemini Omni Turns Anything Into Video — An “Omni” logo surrounded by icons for image, video, audio, and text, promoting multimodal integration.
- [38] Google Unveils Veo 2: Advanced AI Video Generation... — An official-looking Veo2 banner with the phrase “state-of-the-art video generation model” and a lineup of live-action and animated sample shots.
- [43] Introducing Luma Dream Machine - Next Generation AI Video — Extreme close-up of an eye with “Dream Machine” typography, a symbolic image emphasizing photorealistic generation.
- [47] 'Amuse 3.0', an AI art creation tool that includes... — An AMD local AI art tool. Its demo uses a photorealistic portrait of an elderly fisherman, promoting serious on-GPU generation. One of the few specifically named open-source/local-oriented tools.
- [40] Top AI Video Generators of 2025 — A neon comparison chart sorting ChatGPT Plus, Midjourney, Runway, Pika, Kaiber, and others into “image-quality priority” and “free priority” categories. Practical tool-selection information.
- [20] 'AI is getting scary good.' — A warning-style infographic covering AI video generation, voice detection, and prompt engineering, advancing the message “don’t trust appearances alone” as generative-AI literacy.
Signals
- On Pinterest, closed-source news thumbnails for OpenAI, Google Veo/Gemini Omni, Meta Muse, Grok, Midjourney, Runway, and Pika are overwhelmingly dominant. The “surprised face + logo wall” format, seemingly pinned directly from YouTube thumbnails, dominates. The emphasis is on click appeal rather than information depth.
- Open-source and local generation receive little attention. The only concrete names found were Stability AI—though only in the title, paired with an unrelated mood-board image—and AMD Amuse 3.0, a local GPU tool. There were no community-driven technical visuals involving ComfyUI, Hugging Face, or diffusion-model architecture diagrams.
- Photorealistic human generation, featuring faces with wrinkles and highly detailed textures, is repeatedly used by companies as a benchmark-style visual for “this is what we can do now,” signaling technical maturity.
- A meaningful share of infographics address distrust and verification of AI-generated content—fake detection, voice authentication, and ethics—making concern about how to spot and use generated content as visible as the generation news itself.
- What is notably absent: pins directly covering specific open-source model names such as Stable Diffusion, FLUX, Wan, or HunyuanVideo; screenshots of GitHub or technical blogs; and pins showing research papers or benchmark metrics. Pinterest’s format favors secondary news roundups, comparison charts, and ad-like banners rather than primary information from technical communities.
Limits
output/pinterest.pins.mdhad no genre categorization (genrewas blank), and was provided as a single set of 50 items. The playbook’s expected genre-by-genre summary was therefore not possible, so the set was analyzed as a whole.- Of 50 pins, 18 images were opened and reviewed, selected to reflect title specificity and topic diversity. The remaining 32 were not reviewed, but repeated formats were strong enough in the inspected sample for the overall pattern to be clear.
- Several pins had mismatched titles and images—for example, pin
[29]had a Stability AI-related title but an unrelated mood-board image. Such pins were discussed according to their title context rather than image content. - Pinterest was not browsed directly; only the worker’s pre-collected images and titles were available. Actual engagement measures such as saves and likes, as well as the bodies of linked articles, could not be confirmed.
Recommended actions
- Re-run the X stage with direct AI keywords (Midjourney, Sora, Nano Banana, ComfyUI, Flux) instead of generic trending topics.
- Keep watching the Qwen-Image-2.1 ecosystem (WebUI, LoRA, ControlNet) as a leading indicator of open-source momentum.
- Track Sora 2's cost-versus-revenue gap as a proxy for closed-source video generation profitability.
- Map which tools users switch to when a closed-source tool tightens its guardrails.
- Expand Pinterest sampling beyond 18 of 50 pins, or find a way to retrieve engagement counts.
- Treat Lemmy's !ai_reddit community as a Reddit mirror, not an independent signal, when weighing its findings.
Collected images





























Data quality notes
The X stage collected posts from generic trending topics rather than AI-related searches and contributed nothing; YouTube and Pinterest could not confirm engagement metrics (views/subscribers or saves/likes) due to JavaScript rendering and sampling limits, while Reddit and Bluesky were based on real collected/API data and are the most reliable sources here.